[Maeumjigi Capstone Dev Log #12] 70B Massive Model Fine-Tuning and GPU Memory (OOM) Struggle

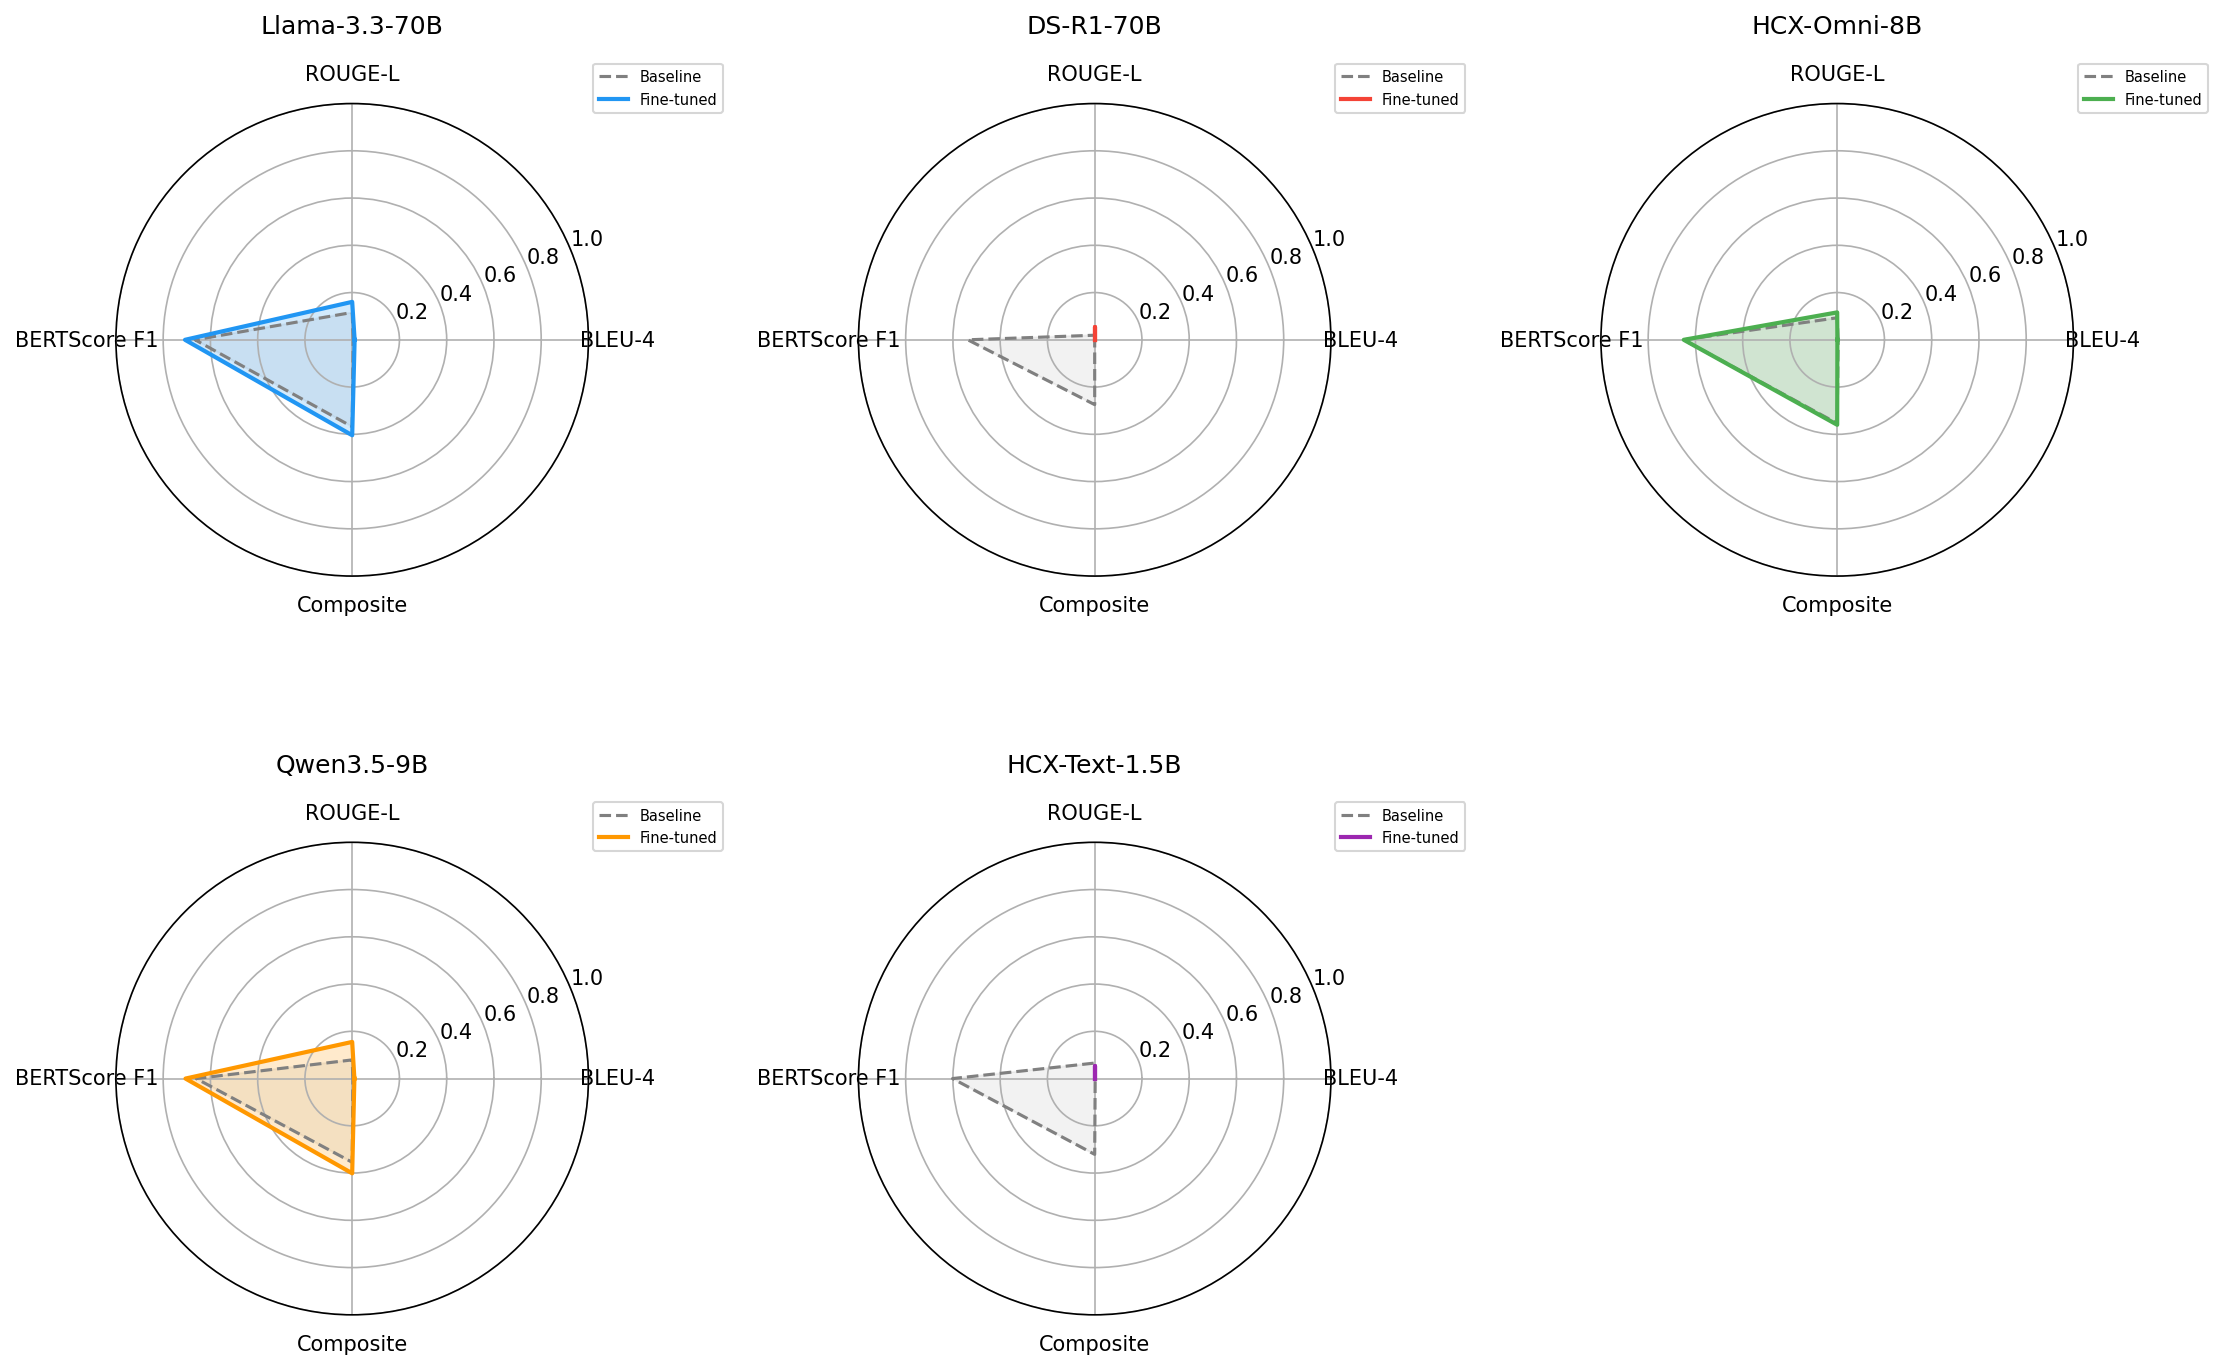
On May 3, having gained enough experience with the 8B models, our team finally challenged the ultimate kings of performance: fine-tuning massive 70B (70 billion parameters) models. We attempted to train both Llama 3.3 70B and DeepSeek-R1 70B, but as expected, we hit a massive hardware resource wall.
70B Models and the Terror of OOM (Out of Memory)
- Problem: As soon as we ambitiously uploaded and ran the 70B fine-tuning code on the server, errors started popping up.
- Process:
"I copied the server's fine_tuning folder and sub-files. Please check the copied files and identify the cause of the error." "Do we not need to modify DeepSeek's 70B model? Please check for potential errors."
- Result: Our brief moment of relaxation, analyzing
train_log.jsonland asking for estimated completion times, was shattered when the 70B models instantly devoured all the GPU memory. (OOM error occurred!)
The GPU Memory Diet Operation
- Problem: "The GPU memory usage is already at MAX." We had to somehow reduce the memory usage so the training wouldn't crash.
- Process:
"Modified to save_steps = 50, save_total_limit = 10, eval_steps = 50, patience = 10." "Please evaluate the configured early stopping conditions." "I set the max_seq_length of both 70B models to 512 in ft_configs.yaml, but the server's nvitop still shows memory usage at max. Why is that?"
- Result: We drastically reduced the context length processed at once (
max_seq_length) to 512 and heavily modified hyperparameters to reduce unnecessary saving. However, monitoring withnvitopshowed that VRAM was still gasping at its absolute limit. Eventually, the horrific phenomenon of the training freezing around steps 100 and 150 repeated itself.
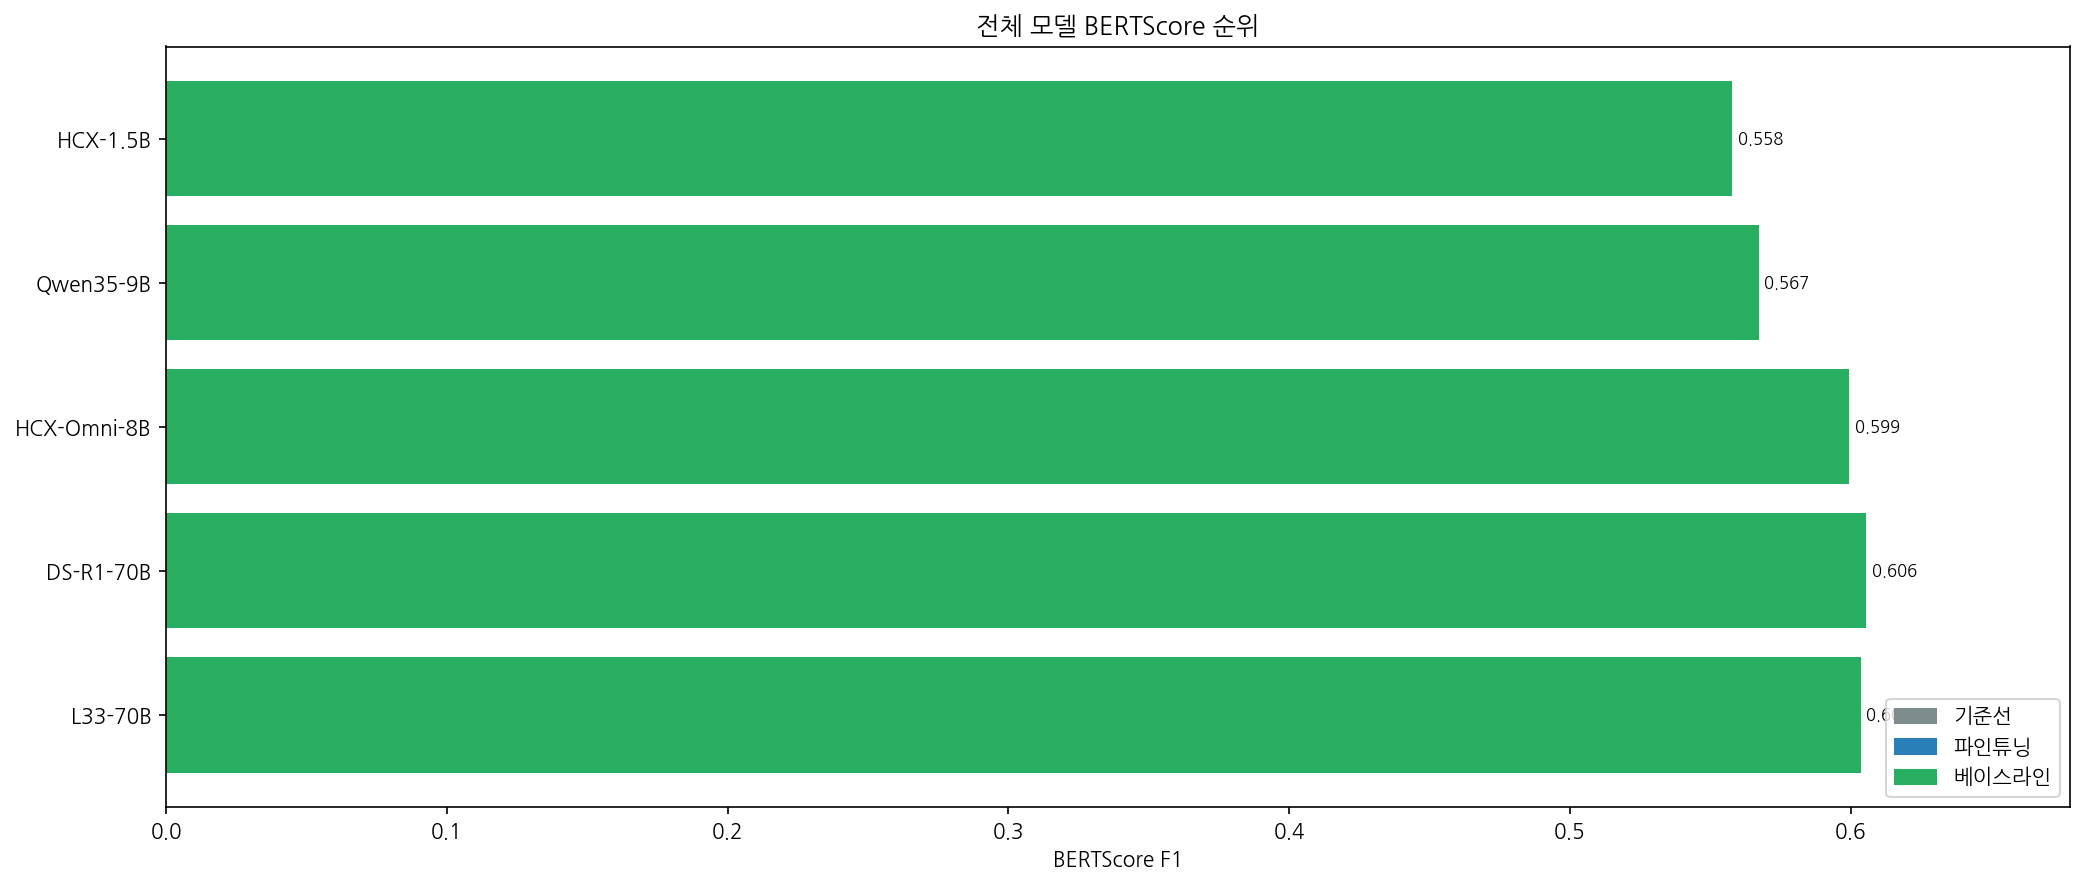
Taming a massive beast like 70B is truly not easy. We are constantly throwing error logs at the Artificial Intelligence (AI) to find solutions, but it seems we need endless testing to see if we can overcome the physical VRAM limits with software optimization techniques (LoRA, Quantization, etc.). Will we succeed in fine-tuning the 70B models? To be continued in the next log!