[Maeumjigi Capstone Dev Log #18] Expanding Inference Tokens and Comparing 2nd Fine-Tuning Results

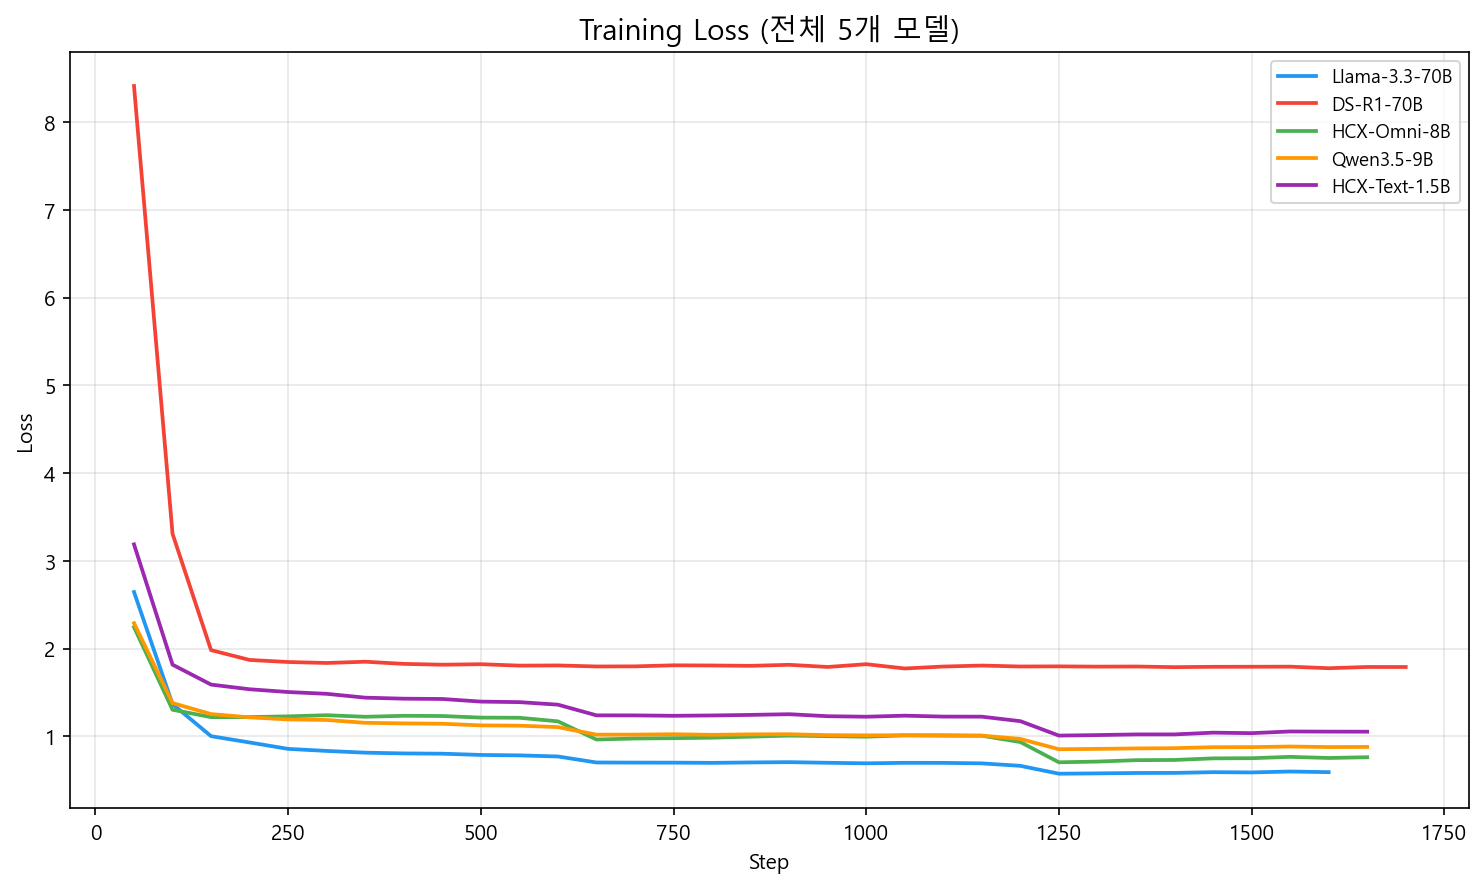
On May 13th, after fixing the hardcoding bugs discovered yesterday, we finally resumed proper inference testing for the 2nd round fine-tuned models.
The Cause of Short Answers: Increase the Token Length!
While meticulously reviewing the inference results, I felt that the answers from the Llama33-70B_a8 model were still strangely short and rigid.
"This is one of Llama33-70B_a8's answers. I feel that max_seq_length and max_new_tokens are too small. I want to increase them. Looking at the VRAM status, how much can I increase them?"
After calculating the available VRAM space (39.8GB at the time) with the Artificial Intelligence (AI), we boldly increased max_new_tokens (the maximum number of words generated) to 384. The result was a massive success!
[Before] "It must be really hard to feel that way. It is important to talk to a professional."
[After] "It must be really hard to feel that way. However, having these thoughts is not a sign that you are weak, but a signal that you are carrying too much burden right now. I highly recommend slowly unraveling these emotions with a professional."
By simply increasing the token allowance, the model maintained its context to the end and began pouring out much deeper and warmer sentences of empathy. The model had been holding its tongue because it was trapped in a limited token count.
Alpha Value Comparison Analysis (a=8 vs a=16)
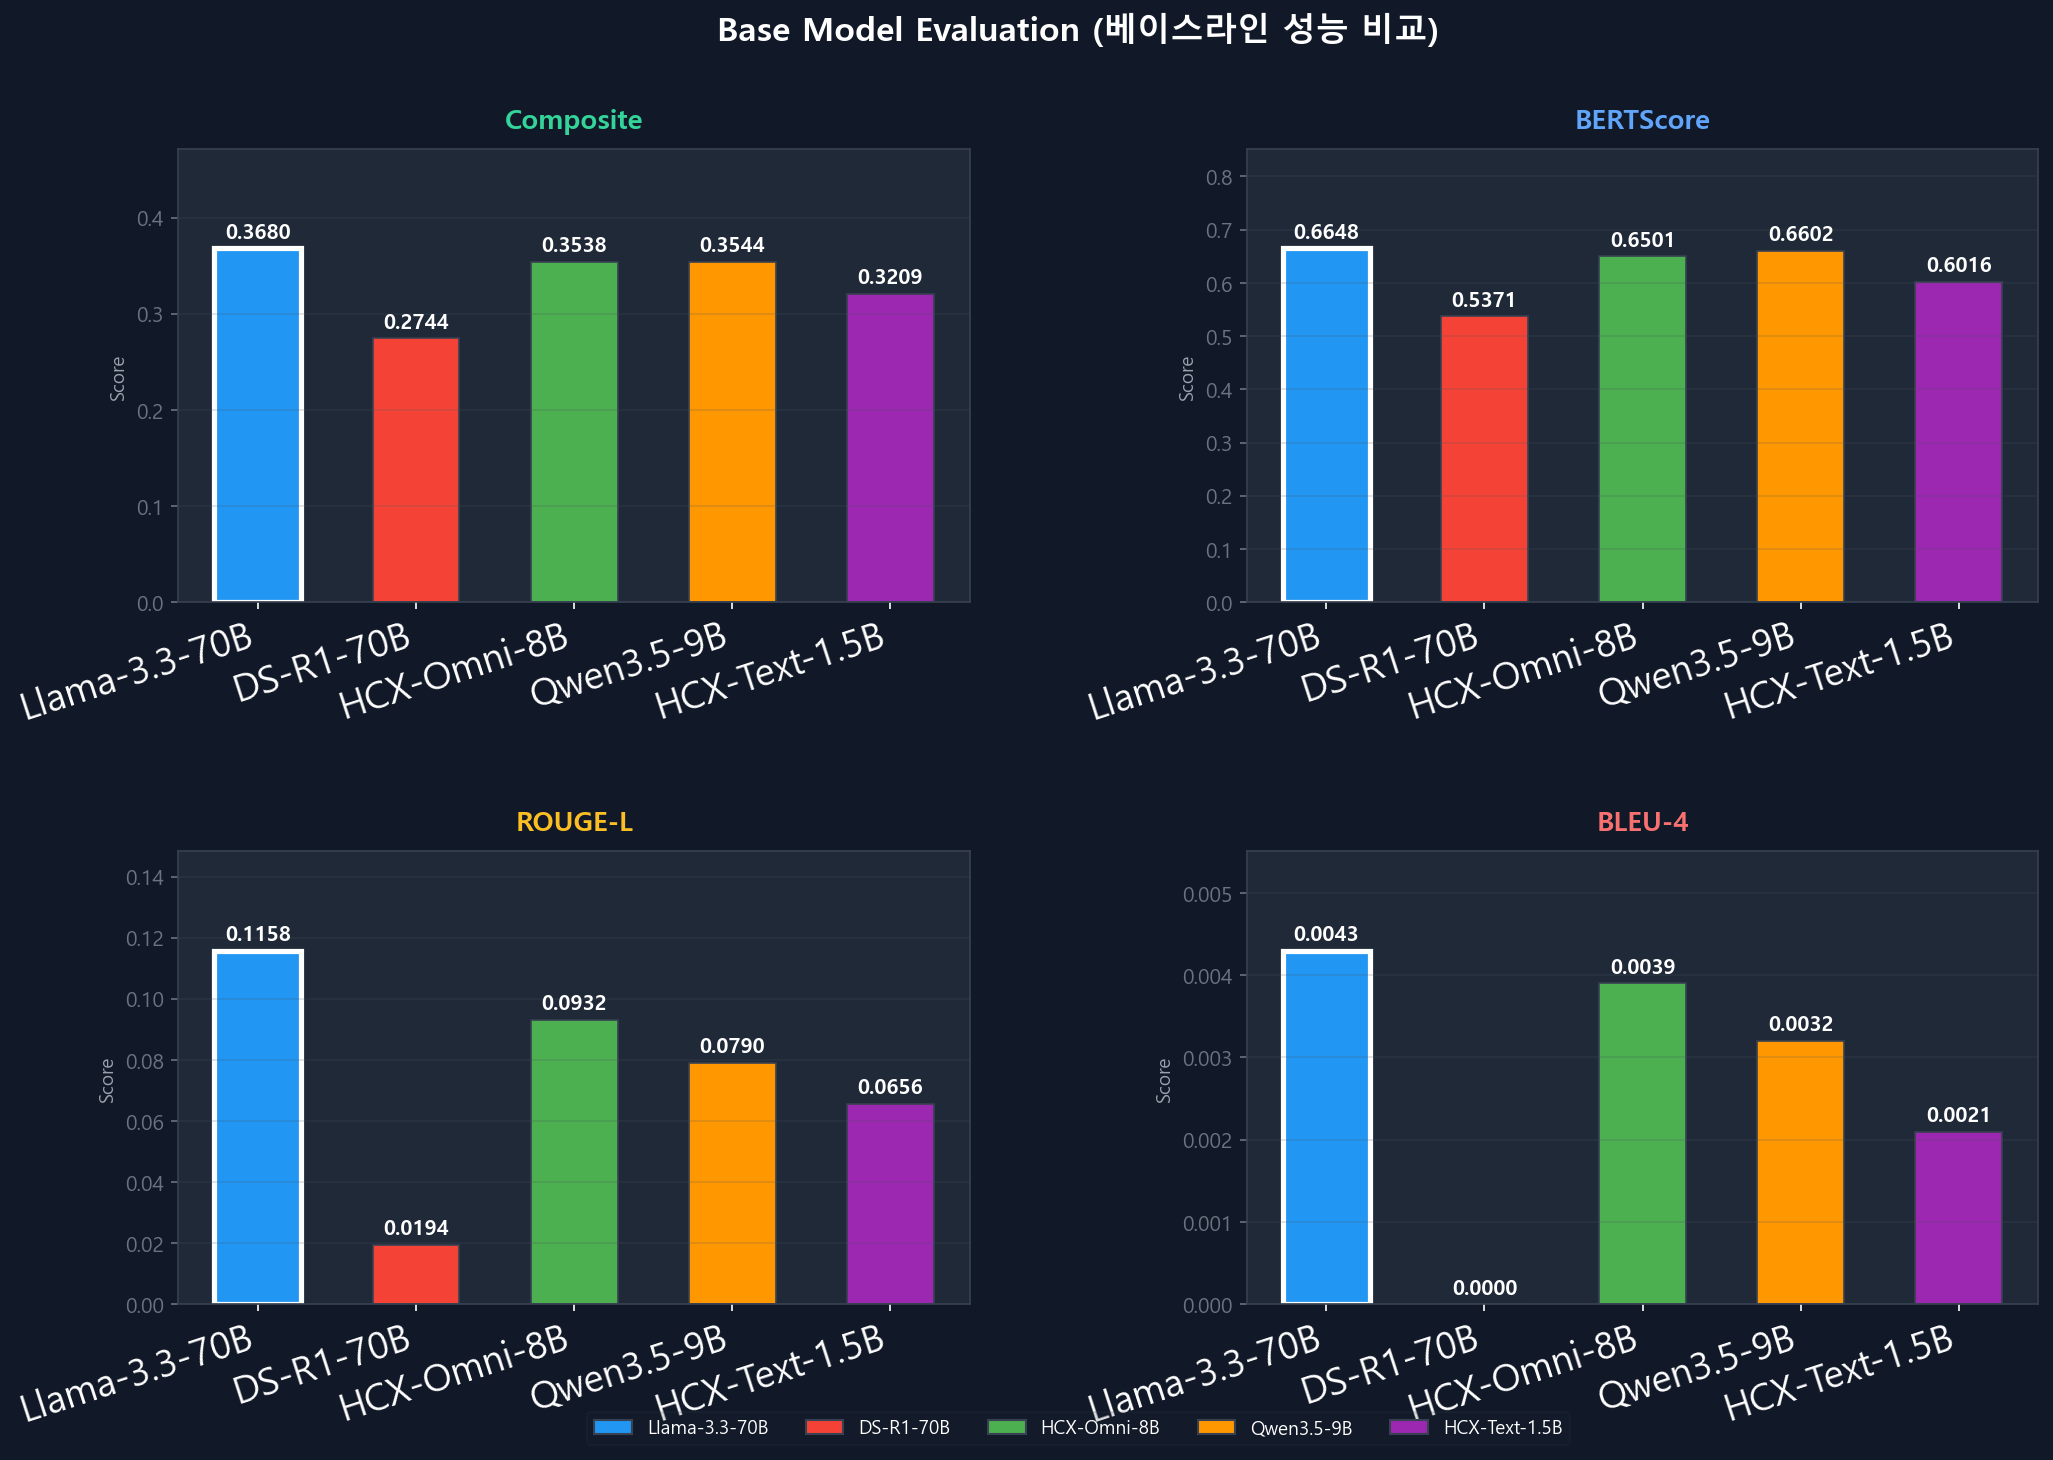
The results for the biggest objective of the 2nd fine-tuning—the performance difference based on the LoRA hyperparameter alpha—were also out. By analyzing the logs piled up in the fine_tuning_2 folder, we generated graphs like 05_alpha_comparison_daily.png. With rank=16 fixed, we clearly visualized how the model's overfitting patterns and final answer quality differed when given alpha=8 versus alpha=16.
Ultimately, models granted the correct hyperparameters and ample token length were finally getting closer to the true 'Maeumjigi' (Heart-keeper) we had originally planned. It seems our mid-term presentation preparations will wrap up very smoothly!