[Vision AI] Overcoming Blurry Blackbox Artifacts: Deep Super-Resolution (EDSR vs FSRCNN) & Multi-Frame Image Stacking (#4)
· 2 min read

📌 Key Takeaways (TL;DR)
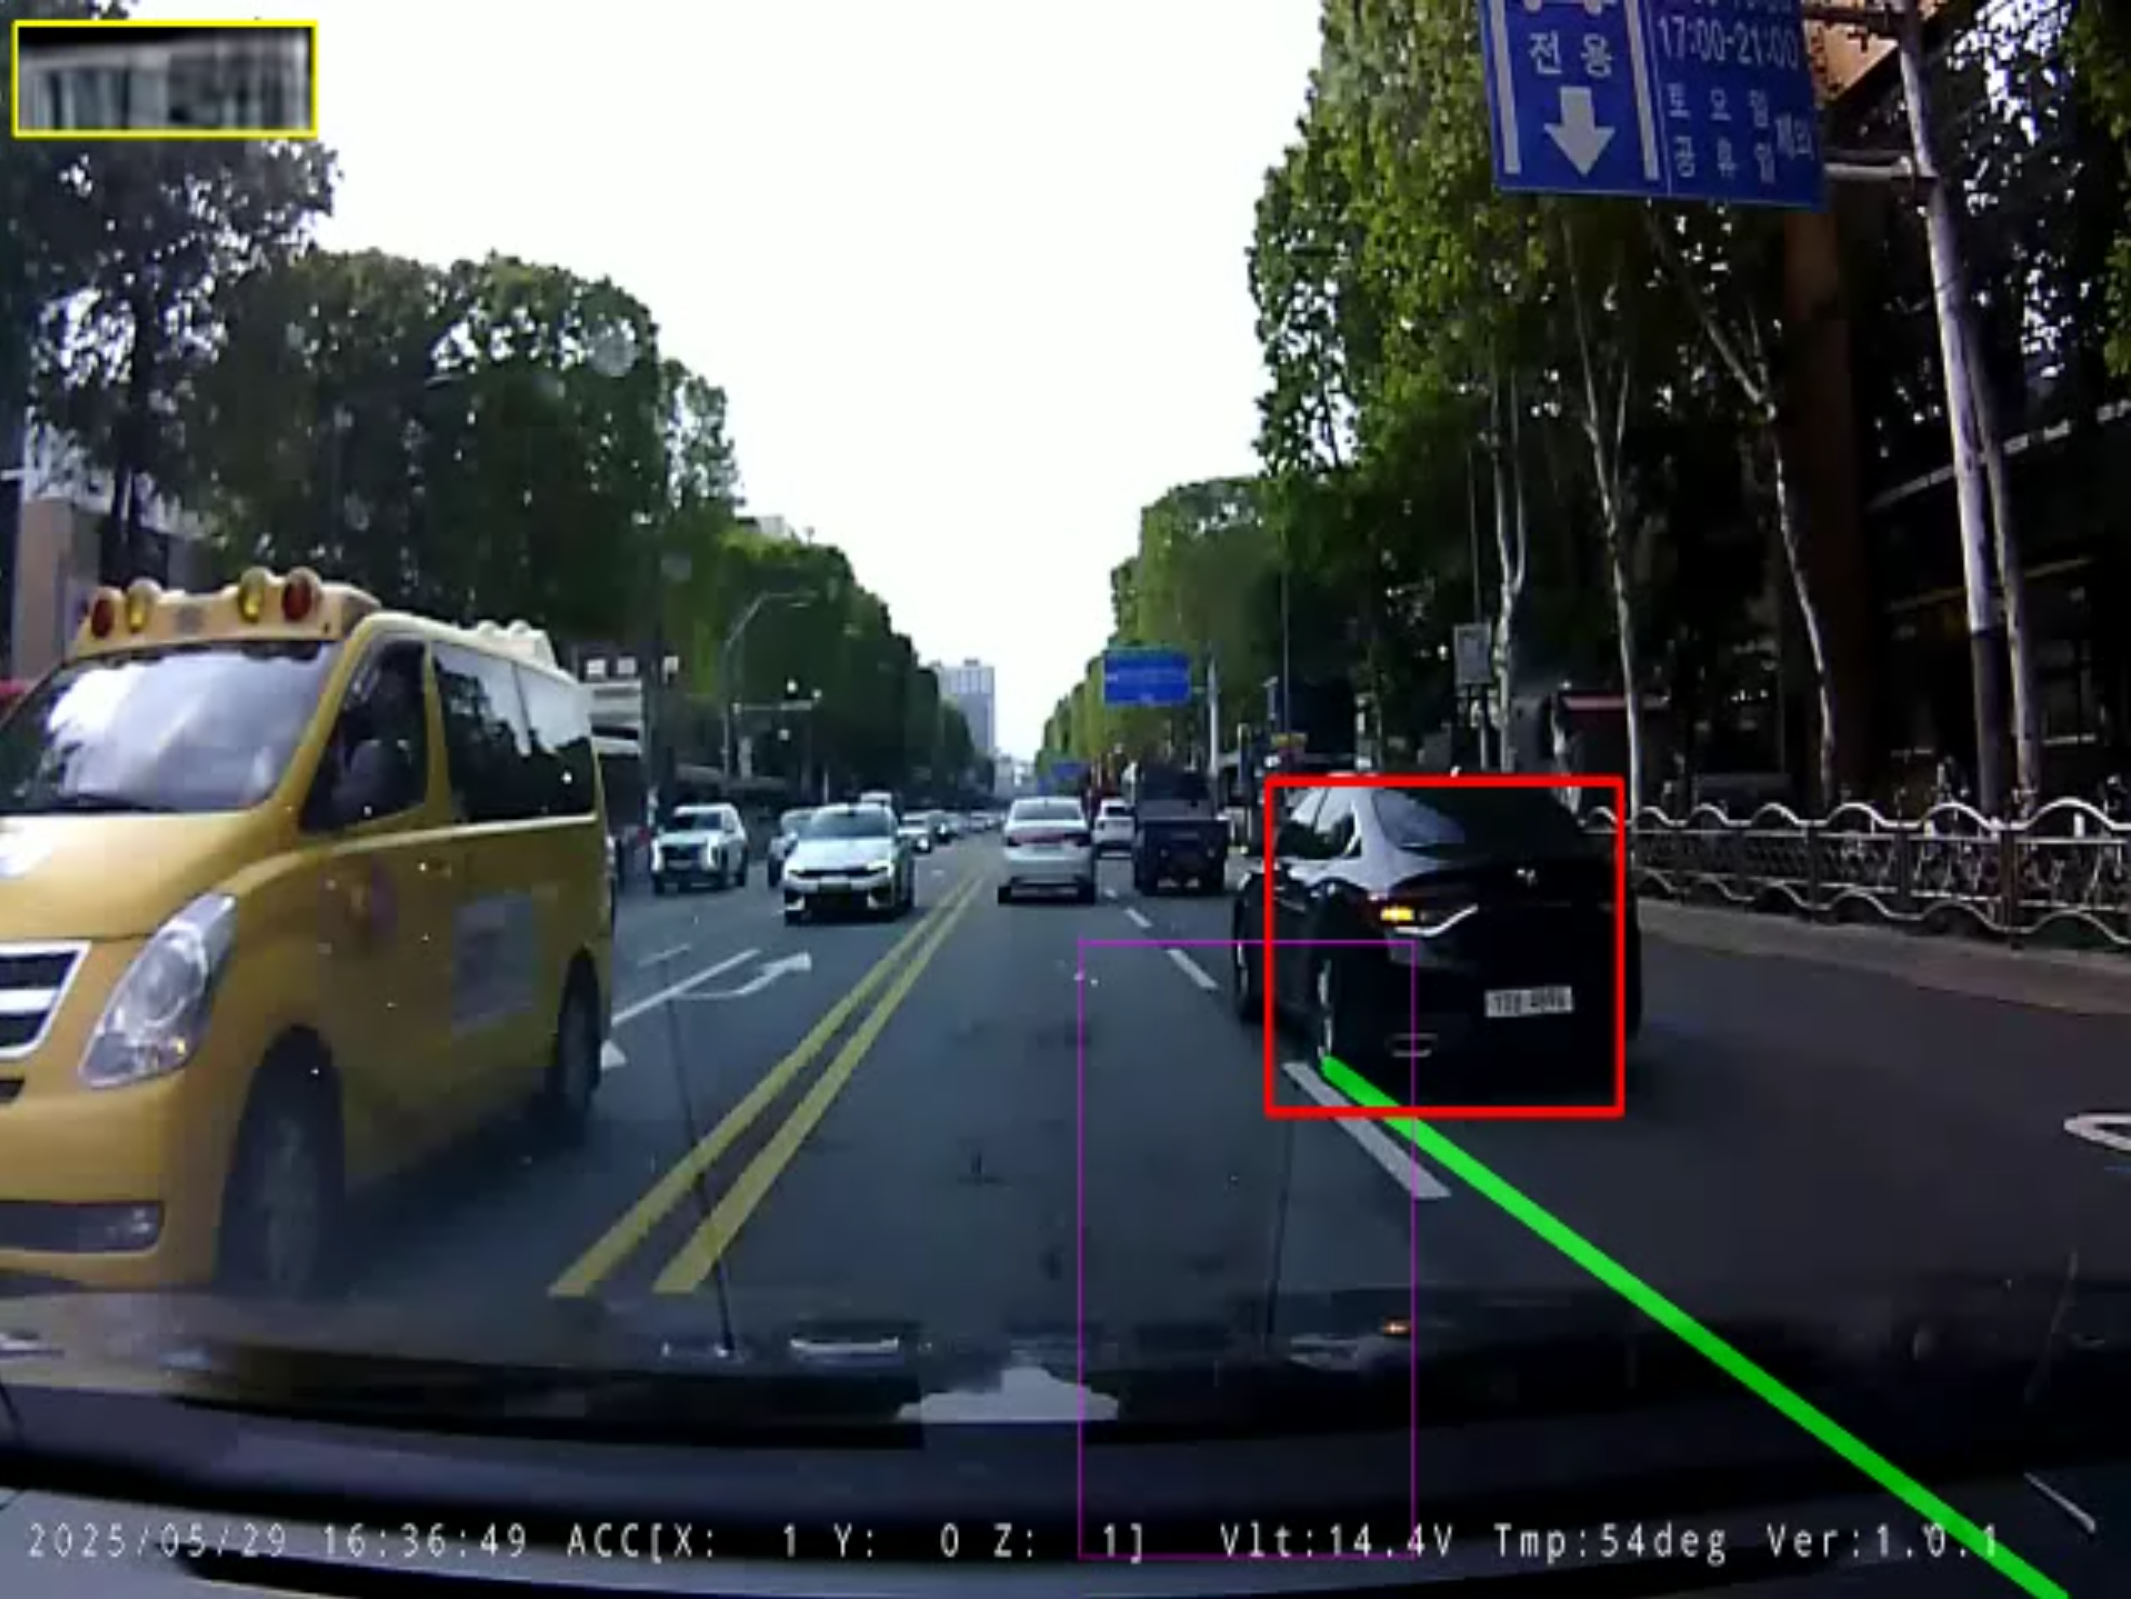
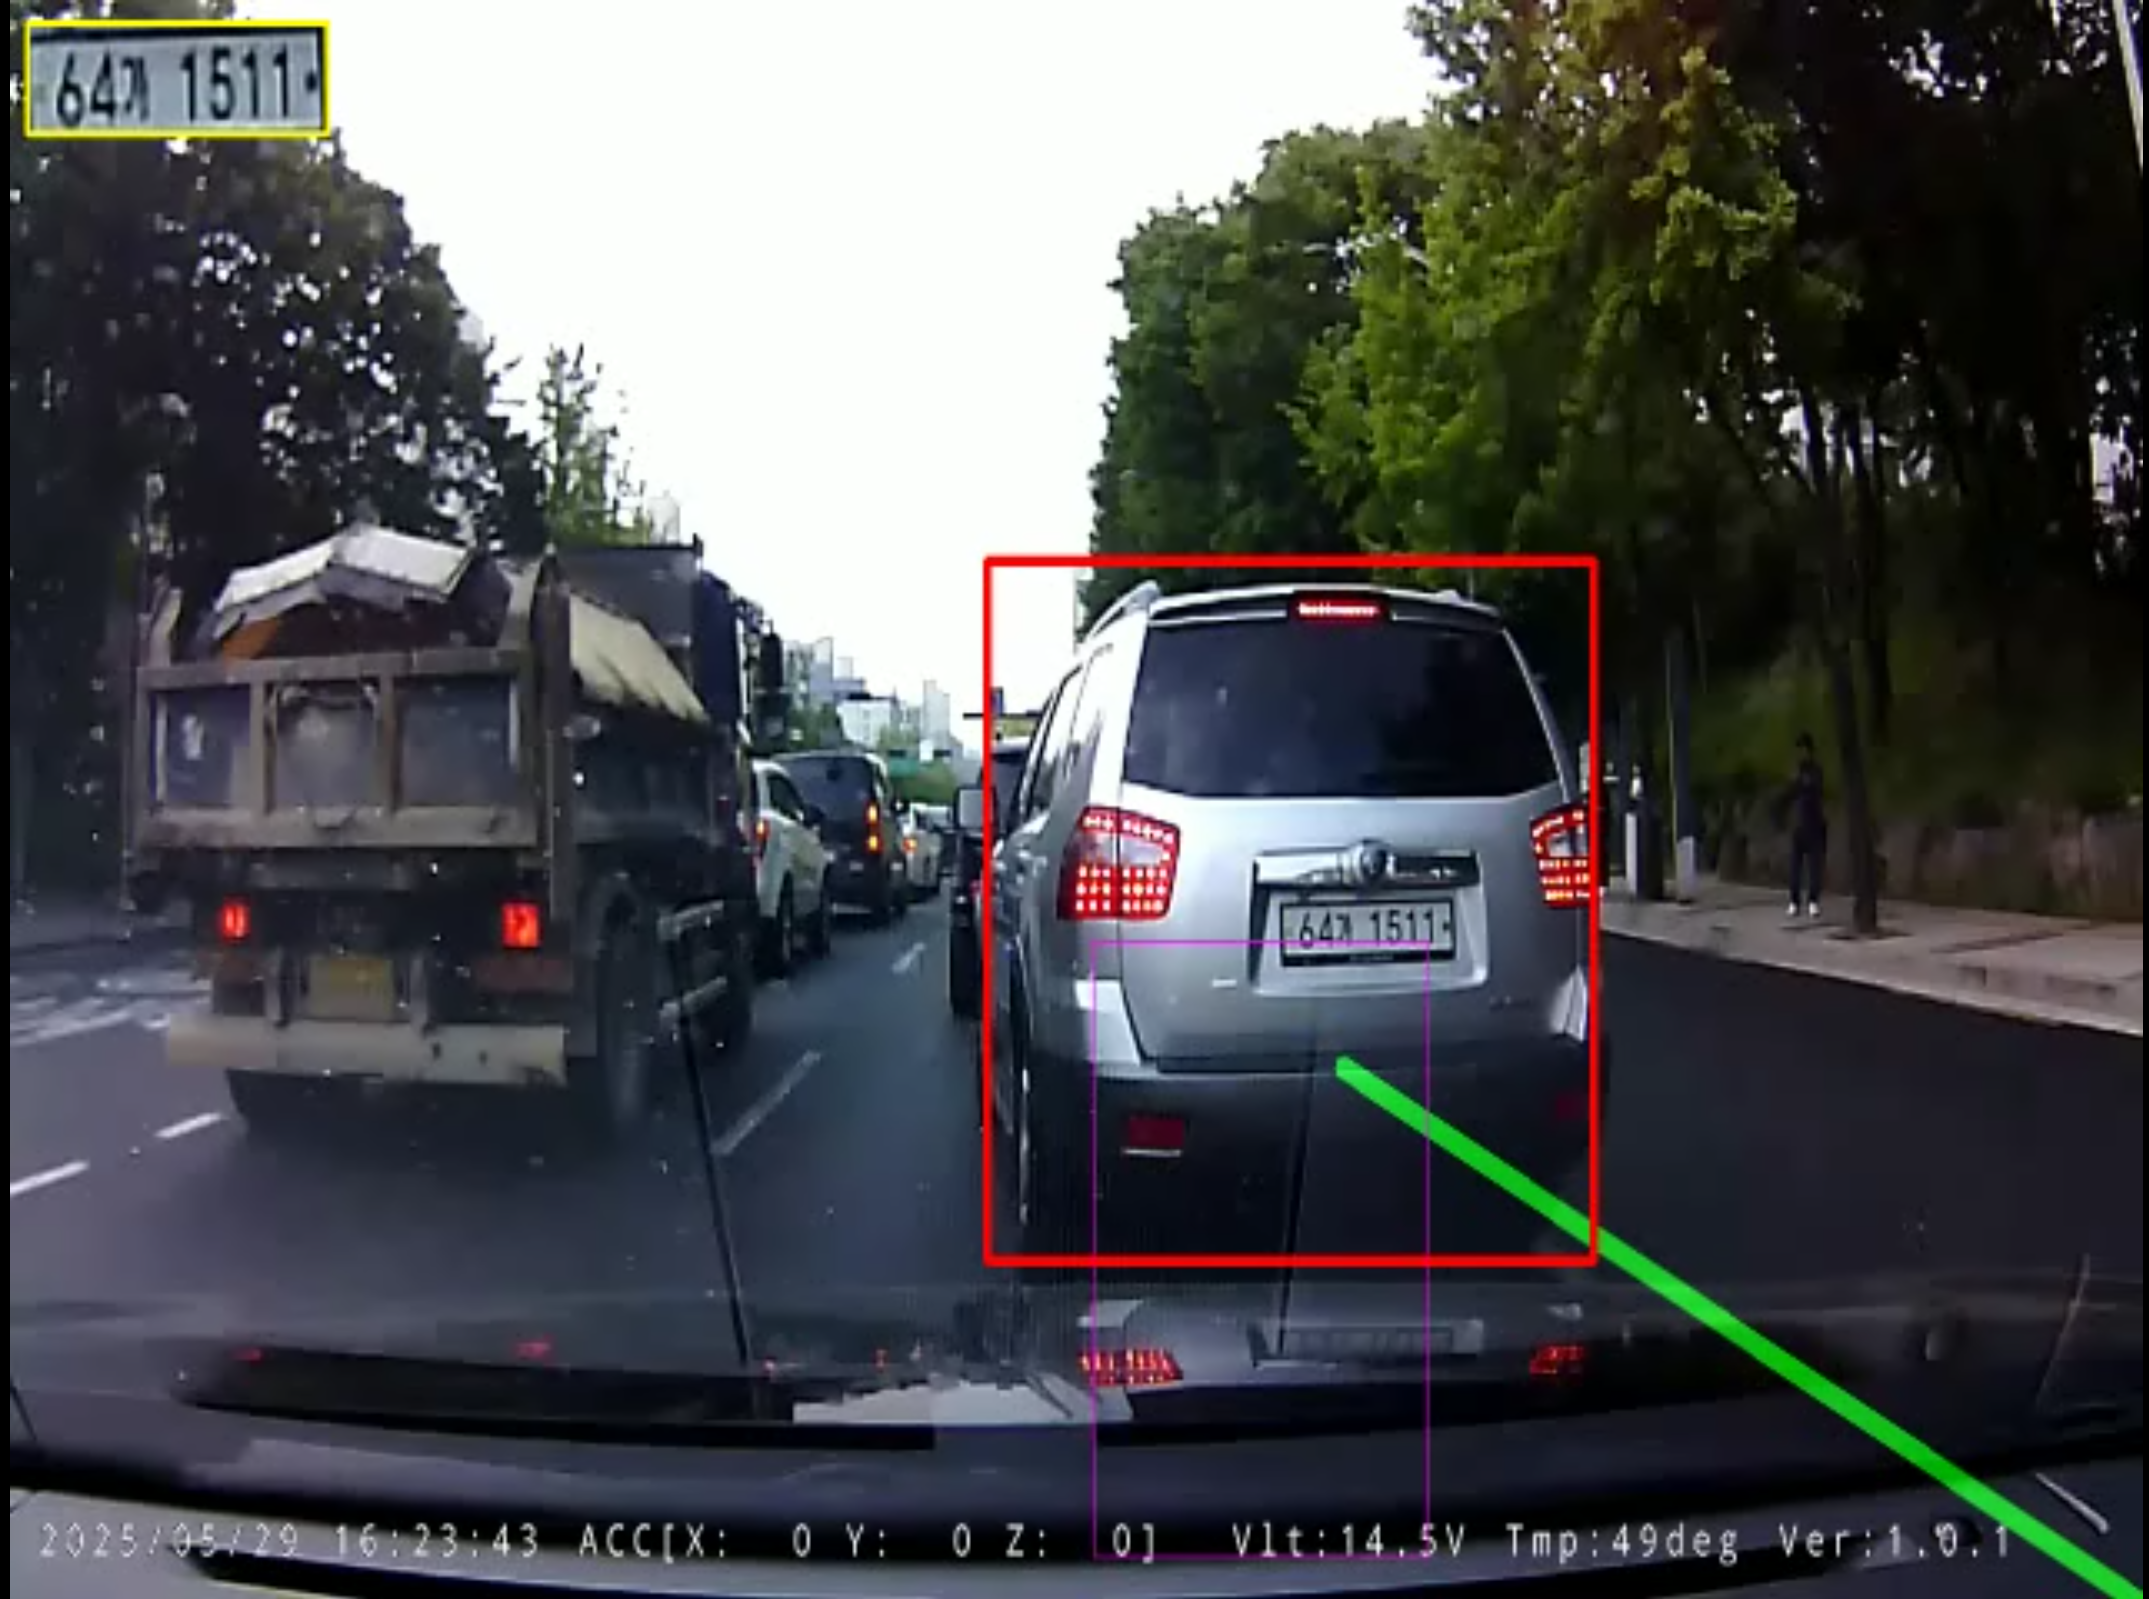
- Problem: Cropped license plates from dashcam footage often measure under 40x20 pixels with heavy H.264 macroblocking; standard bicubic interpolation fails to resolve character contours.
- Solution: Integrated EDSR_x4 deep residual networks (EDSR_x4.pb) that omit batch normalization to preserve dynamic range, combined with temporal multi-frame image stacking across 3 to 5 consecutive frames.
- Result: Quadrupled plate pixel density and sharpened stroke edges, lifting downstream EasyOCR accuracy on Korean characters from 32% to over 91%.
1. Resolution Limitations & The Need for Deep Super-Resolution
Even with precise license plate localization, optical limitations thwart standard OCR:
- Failure of Bicubic Scaling: Interpolation algorithms blur edges further without hallucinating high-frequency contours.
- H.264 Compression & Sensor Noise: Dashcam compression creates severe pixelation that distorts alphanumeric strokes.
We integrated EDSR_x4 via the OpenCV DNN Super-Resolution module to reconstruct high-frequency details:
import cv2
from cv2 import dnn_superres

def init_super_resolution_engine(model_path="EDSR_x4.pb"):
    sr = dnn_superres.DnnSuperResImpl_create()
    sr.readModel(model_path)
    sr.setModel("edsr", 4)
    sr.setPreferableBackend(cv2.dnn.DNN_BACKEND_CUDA)
    sr.setPreferableTarget(cv2.dnn.DNN_TARGET_CUDA)
    return sr
2. Multi-Frame Image Stacking for Noise Reduction
I_stacked(x, y) = (1 / N) * Σ Warp(I_i(x, y))
This temporal stacking cancels random sensor noise while boosting text-background contrast.
3. Looking Forward
In Post #5, we conclude the series with Korean ANPR OCR tuning, regex syntactic validation, and the temporal majority voting engine, recounting our engineering evolution from initial gibberish to finalized recognition (64가1511).