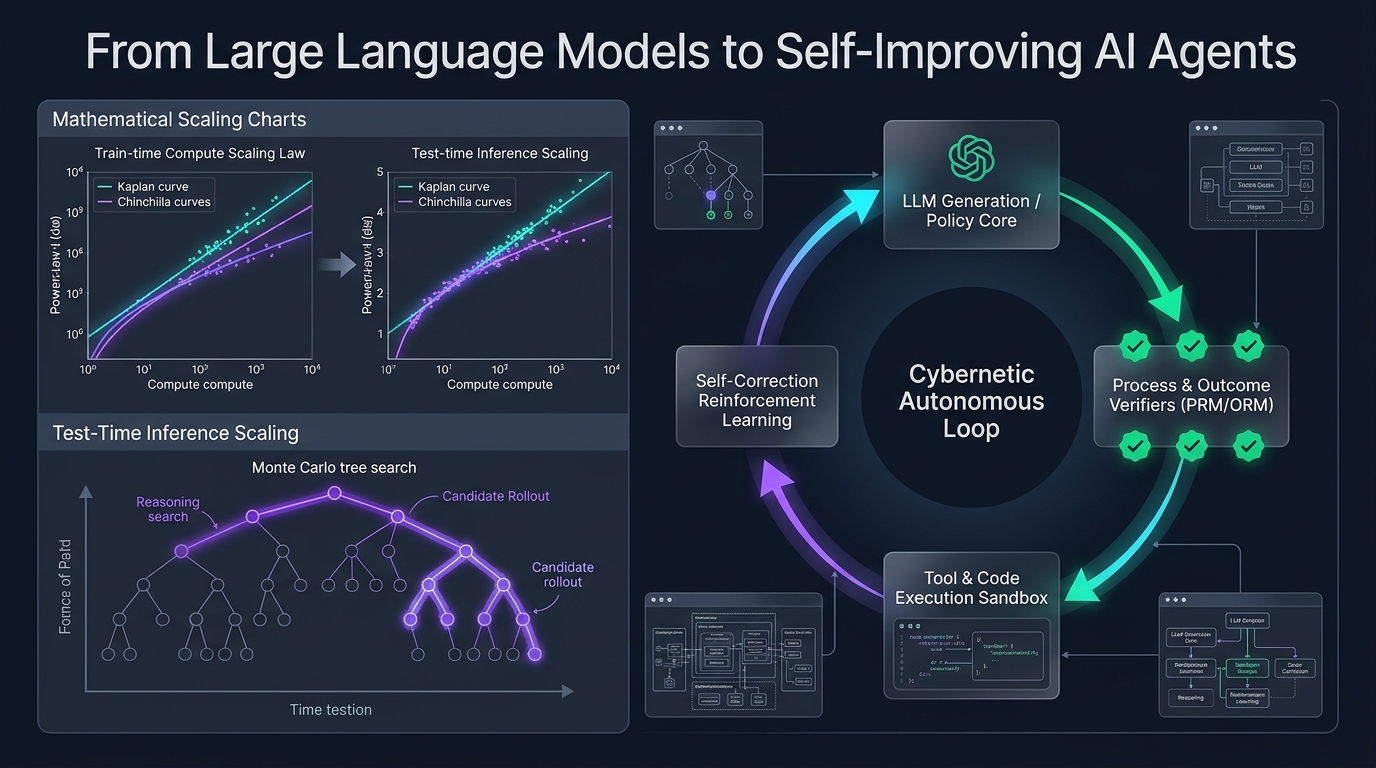
[Stanford CS329A #2] Test-Time Compute Scaling: Beyond Train-Time Scaling Laws to Compute-Optimal Inference

Welcome to the second installment of our definitive engineering breakdown of Stanford University's CS329A: Self-Improving AI Agents (Autumn 2025).
In our inaugural lecture, we traced the macroeconomic paradigm shift from static, autoregressive next-token predictors to autonomous self-improving agentic loops. Today, we confront the technical foundation that makes this autonomy computationally viable: Test-Time Compute Scaling (Inference-Time Scaling).
For over half a decade, the predominant scaling doctrine across the AI industry was dictated by train-time laws (Kaplan et al., Chinchilla): allocate larger clusters, expand parameter footprints, and absorb tens of trillions of tokens. Yet, once a model’s parameters θ are frozen, what happens if we refuse to accept a 50-millisecond greedy response? What if an agent spends 10 seconds, 1 minute, or 10 minutes deliberately exploring reasoning trees, checking intermediate steps, and revising its hypotheses before committing to an action?
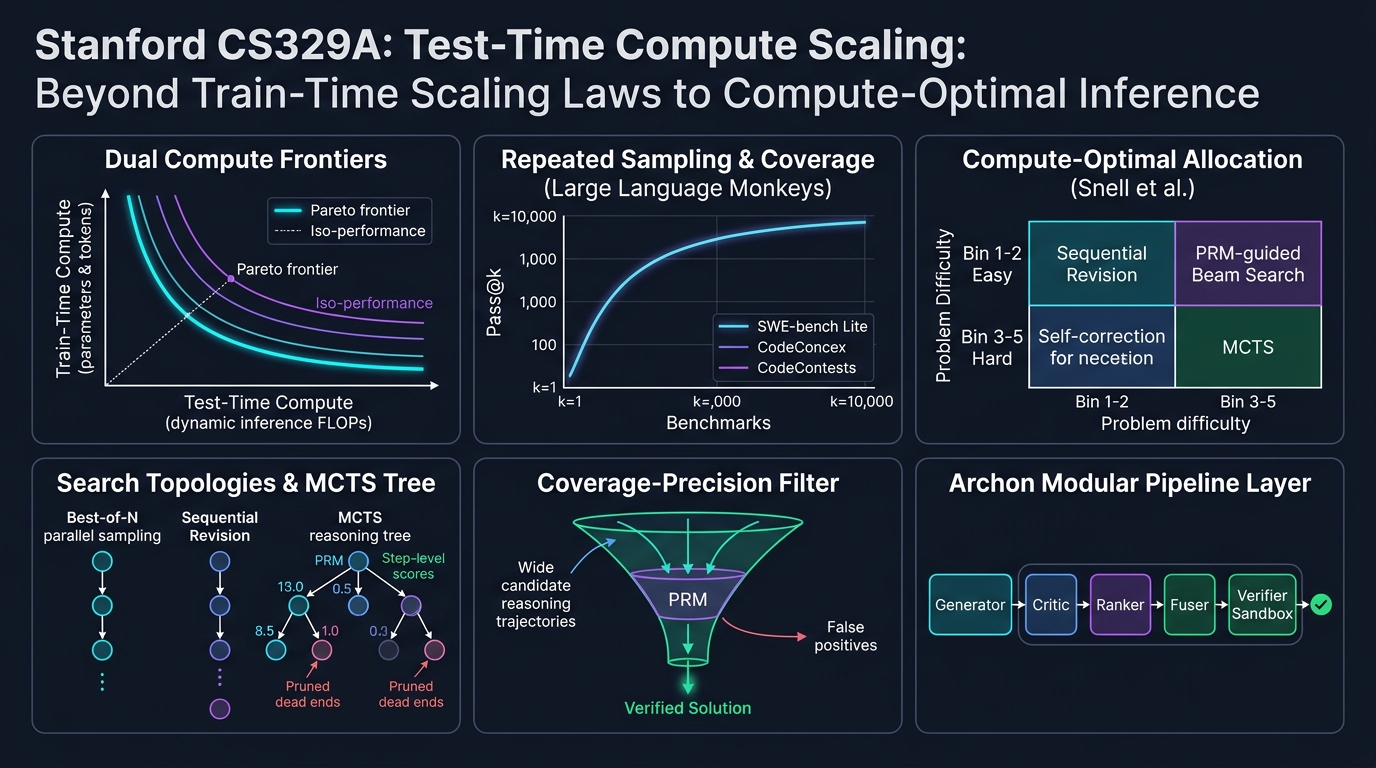
Through the foundational empirical discoveries of Large Language Monkeys (Brown et al., 2024), Snell et al.'s Compute-Optimal Scaling (Stanford/UC Berkeley, 2024), and the Archon modular architecture framework, we will mathematically formalize how trading test-time FLOPs for parameter capacity reshapes modern artificial intelligence.
flowchart TD
    subgraph PreTrain ["The Classical Frontier: Train-Time Scaling"]
        direction TB
        P1["Trillions of Web Tokens (D)"] --> P2["Massive GPU Clusters (C_train)"]
        P2 --> P3["Frozen Dense Model (θ)"]
        P3 --> P4["Single Greedy Forward Pass (O(1) Test Compute)"]
    end

    subgraph TestTime ["The CS329A Frontier: Test-Time Compute Scaling"]
        direction TB
        T1["Frozen Base Weights (θ)"] --> T2["Dynamic Test-Time FLOP Allocation"]
        T2 --> T3{"Adaptive Strategy Selection"}
        T3 -- "Low Difficulty (Bin 1-2)" --> T4["Sequential Revision (Self-Correction)"]
        T3 -- "High Difficulty (Bin 3-5)" --> T5["PRM-Guided Tree Search (MCTS / Beam Search)"]
        T4 --> T6["Process Reward Model (PRM) Verifier"]
        T5 --> T6
        T6 --> T7["Mathematically / Mechanically Proven Solution"]
    end

    PreTrain -.->|"Inflection Point: Parameter Saturation"| TestTime