[Maeumjigi Capstone Dev Log #13] Limits of 70B Training and the Pivot to Mid-Size Models (HCX, Qwen)
· 2 min read

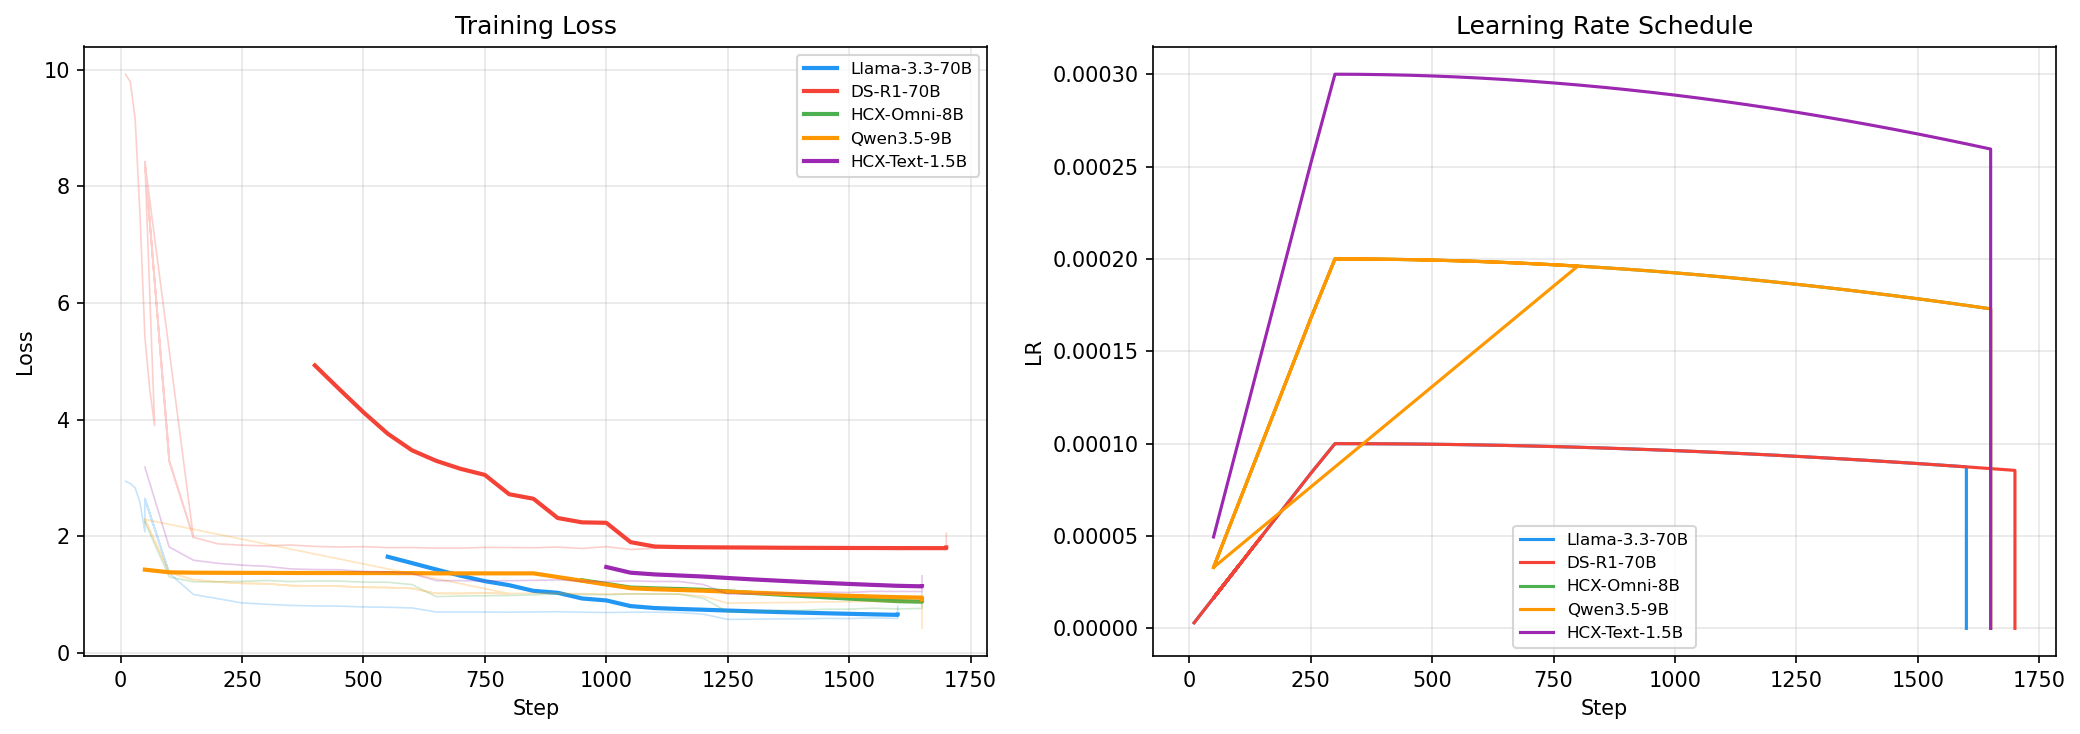
After experiencing the OOM (Out of Memory) hell during the fine-tuning of massive 70B models, on May 4th, we attempted a bold change in strategy. By drastically reducing the batch size, we barely managed to push the 70B models (Llama3.3, DeepSeek-R1) to checkpoint-1200 and 1300, but the training time was absurdly long, resulting in terrible efficiency.