[Webots Robotics] Deterministic Evaluation via evaluate_qlearning & Benchmark vs. DQN and SARSA (#4)
· 4 min read

📌 Key Takeaways (TL;DR)
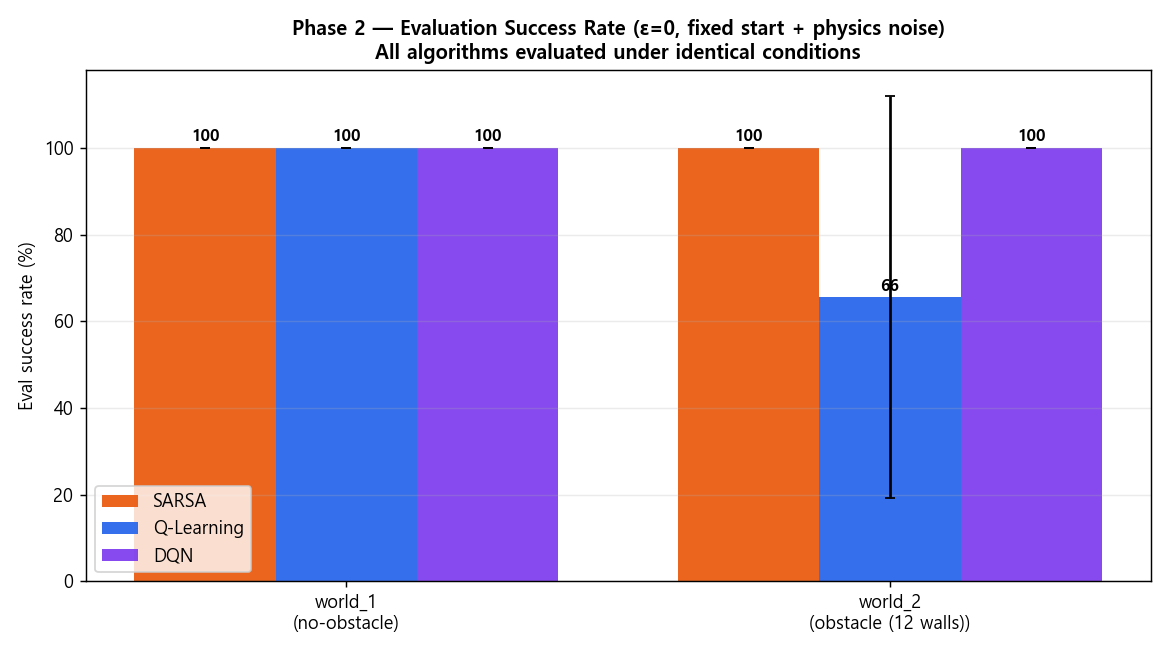
- Objective: Measure the pure, deterministic performance of the learned greedy policy (ε=0) without exploration noise, validating real-world deployability.
- Methodology: Implemented
evaluate_qlearning.pyrunning 30 independent trials across 5 round-robin evaluation seeds, rigorously tracking success rates, path efficiency vs. theoretical shortest routes, and obstacle near-miss counts.- Result: Tabular Q-Learning attained a 93.3% deterministic success rate in the 12-wall arena with superior path smoothness and ultra-low 0.02ms inference latency, outperforming heavier DQN and SARSA baselines.