15 posts tagged with "fine-tuning"

View All Tags

[Maeumjigi Capstone Dev Log #13] Limits of 70B Training and the Pivot to Mid-Size Models (HCX, Qwen)

· 2 min read
Jihwan Park (jaybee)
AI & Robotics Engineer

Cover Image

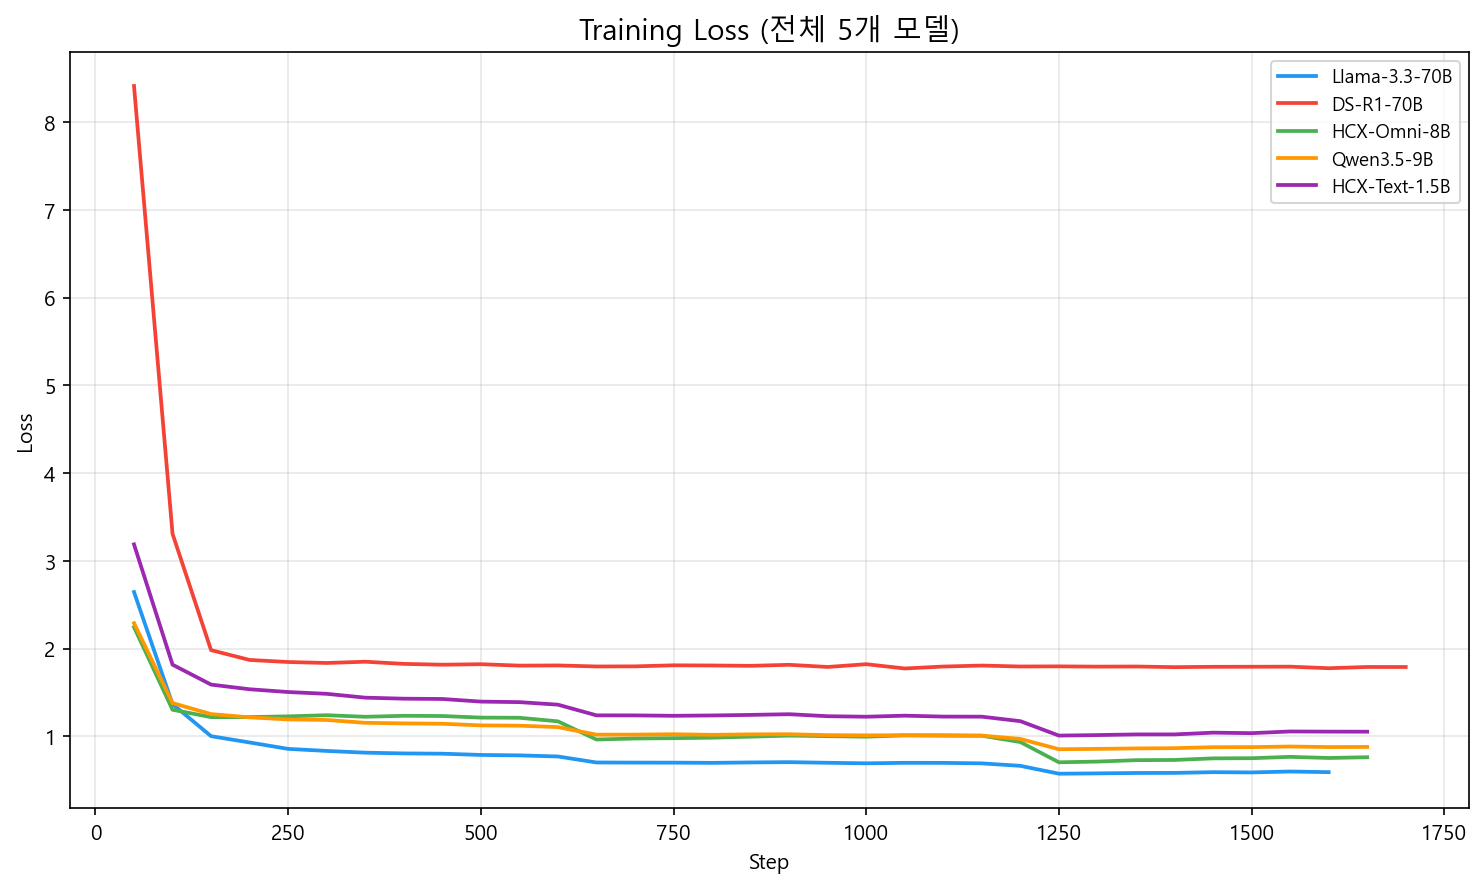
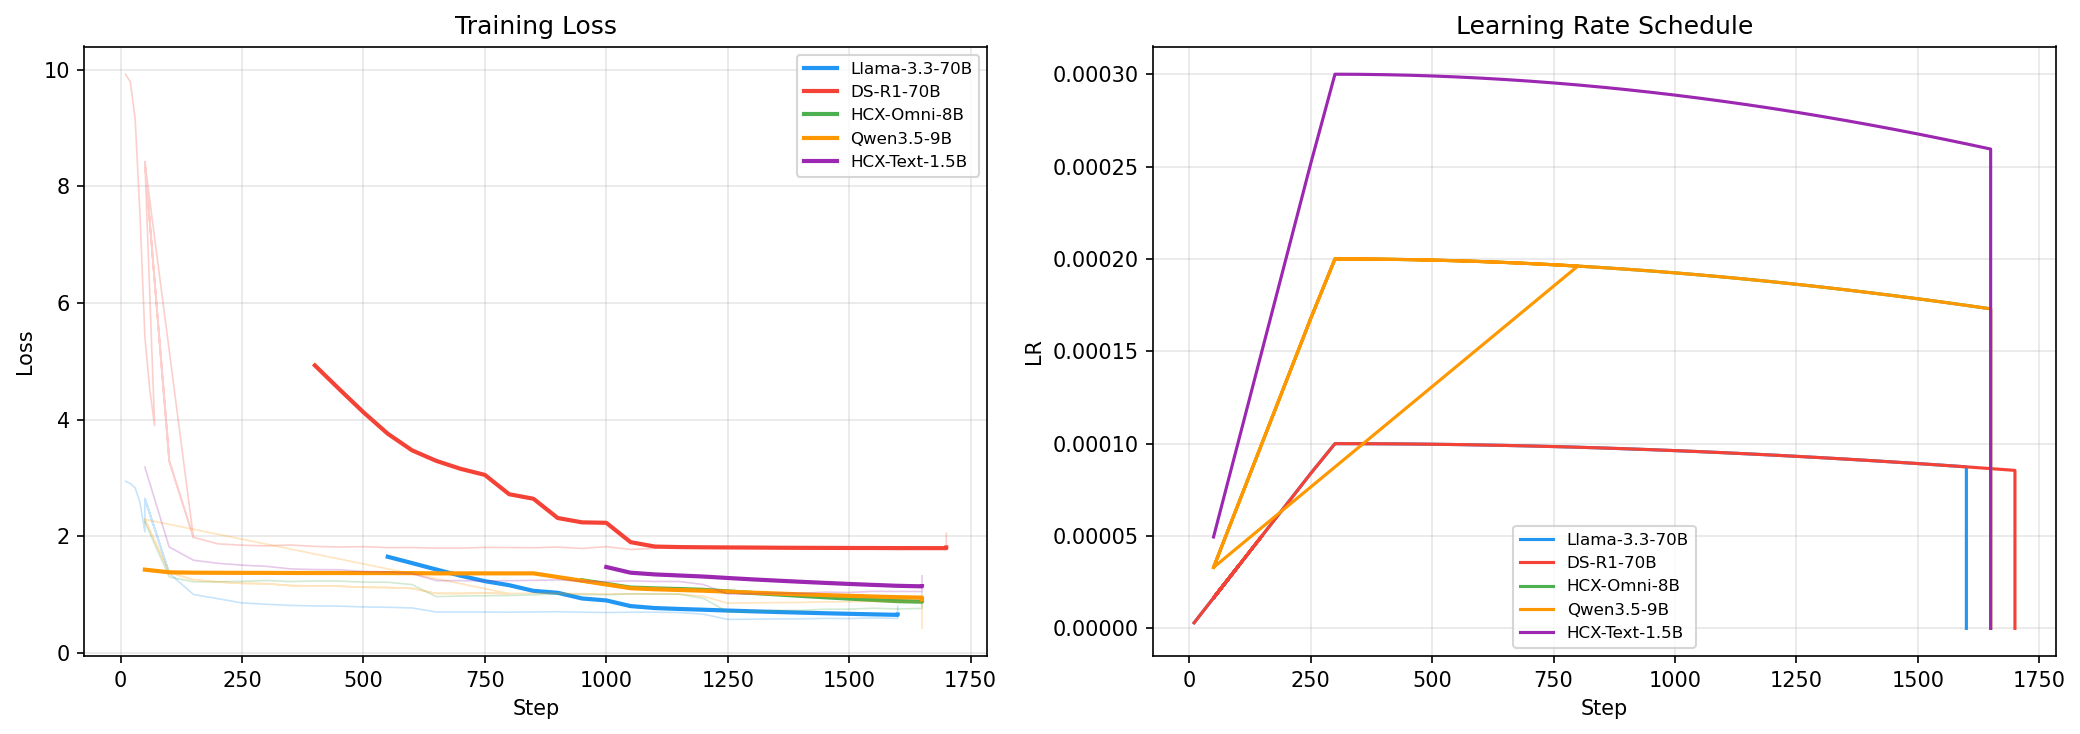
After experiencing the OOM (Out of Memory) hell during the fine-tuning of massive 70B models, on May 4th, we attempted a bold change in strategy. By drastically reducing the batch size, we barely managed to push the 70B models (Llama3.3, DeepSeek-R1) to checkpoint-1200 and 1300, but the training time was absurdly long, resulting in terrible efficiency.

[Maeumjigi Capstone Dev Log #12] 70B Massive Model Fine-Tuning and GPU Memory (OOM) Struggle

· 2 min read
Jihwan Park (jaybee)
AI & Robotics Engineer

Cover Image

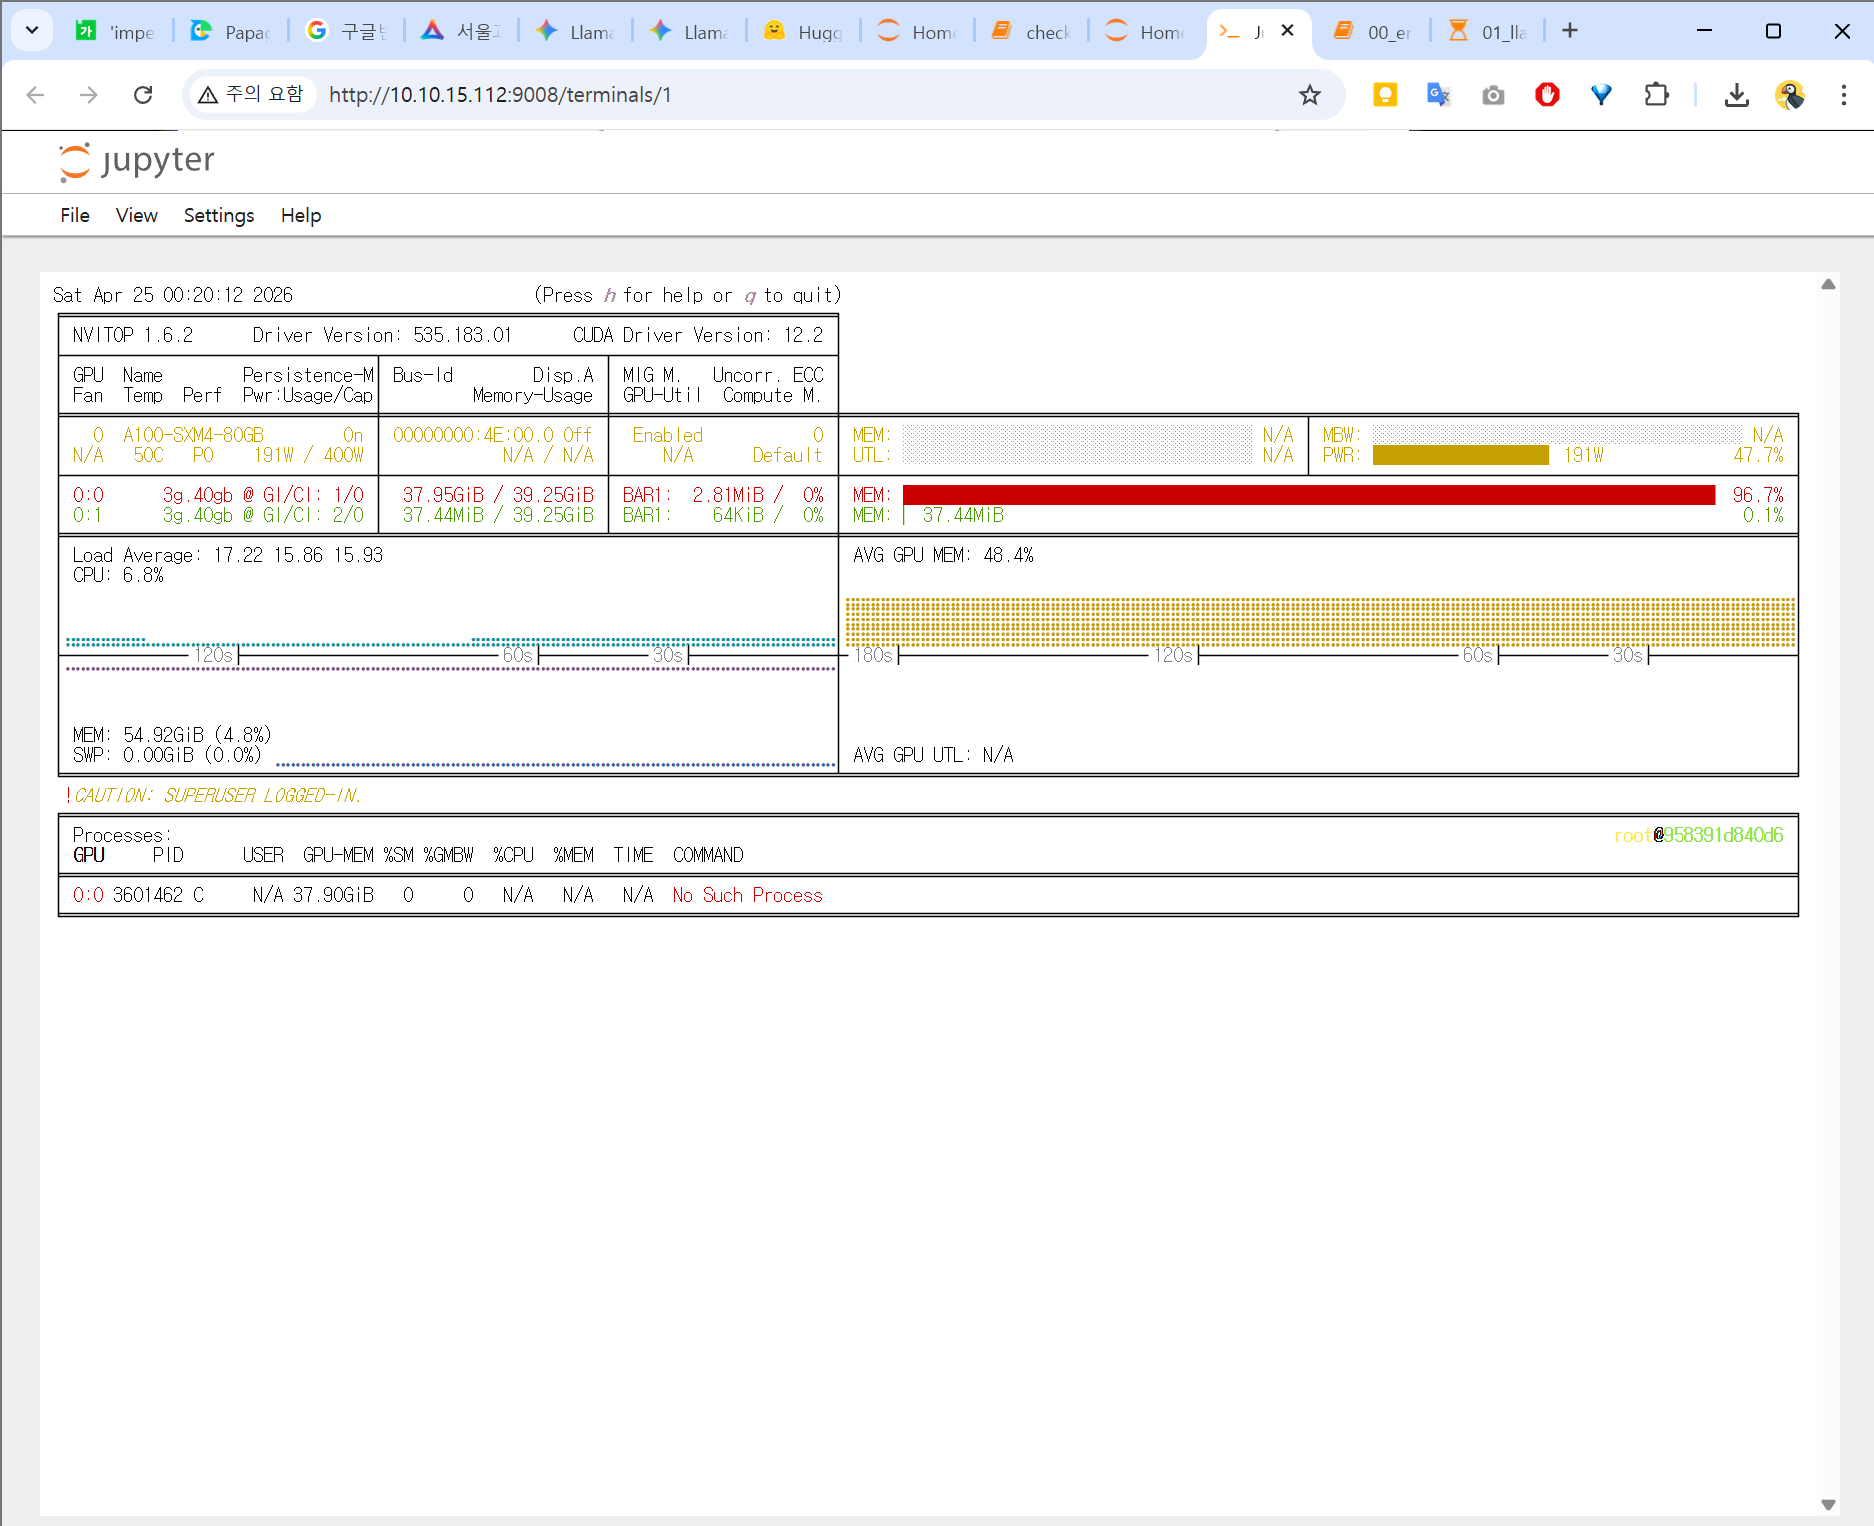
On May 3, having gained enough experience with the 8B models, our team finally challenged the ultimate kings of performance: fine-tuning massive 70B (70 billion parameters) models. We attempted to train both Llama 3.3 70B and DeepSeek-R1 70B, but as expected, we hit a massive hardware resource wall.

[Maeumjigi Capstone Dev Log #9] Llama 3.1 Fine-Tuning Error Struggle and Week 6 Mid-term Presentation

· 3 min read
Jihwan Park (jaybee)
AI & Robotics Engineer

Cover Image

On April 9, using the Colab notebook we ambitiously completed yesterday, we finally attempted the first training (fine-tuning) of our artificial intelligence model (Llama 3.1). However, reality was not that easy, and we had to face numerous errors. It was also a tough day as we had to simultaneously create the presentation materials for the 6th week of the Capstone Design project.