[Maeumjigi Capstone Dev Log #12] 70B Massive Model Fine-Tuning and GPU Memory (OOM) Struggle
· 2 min read

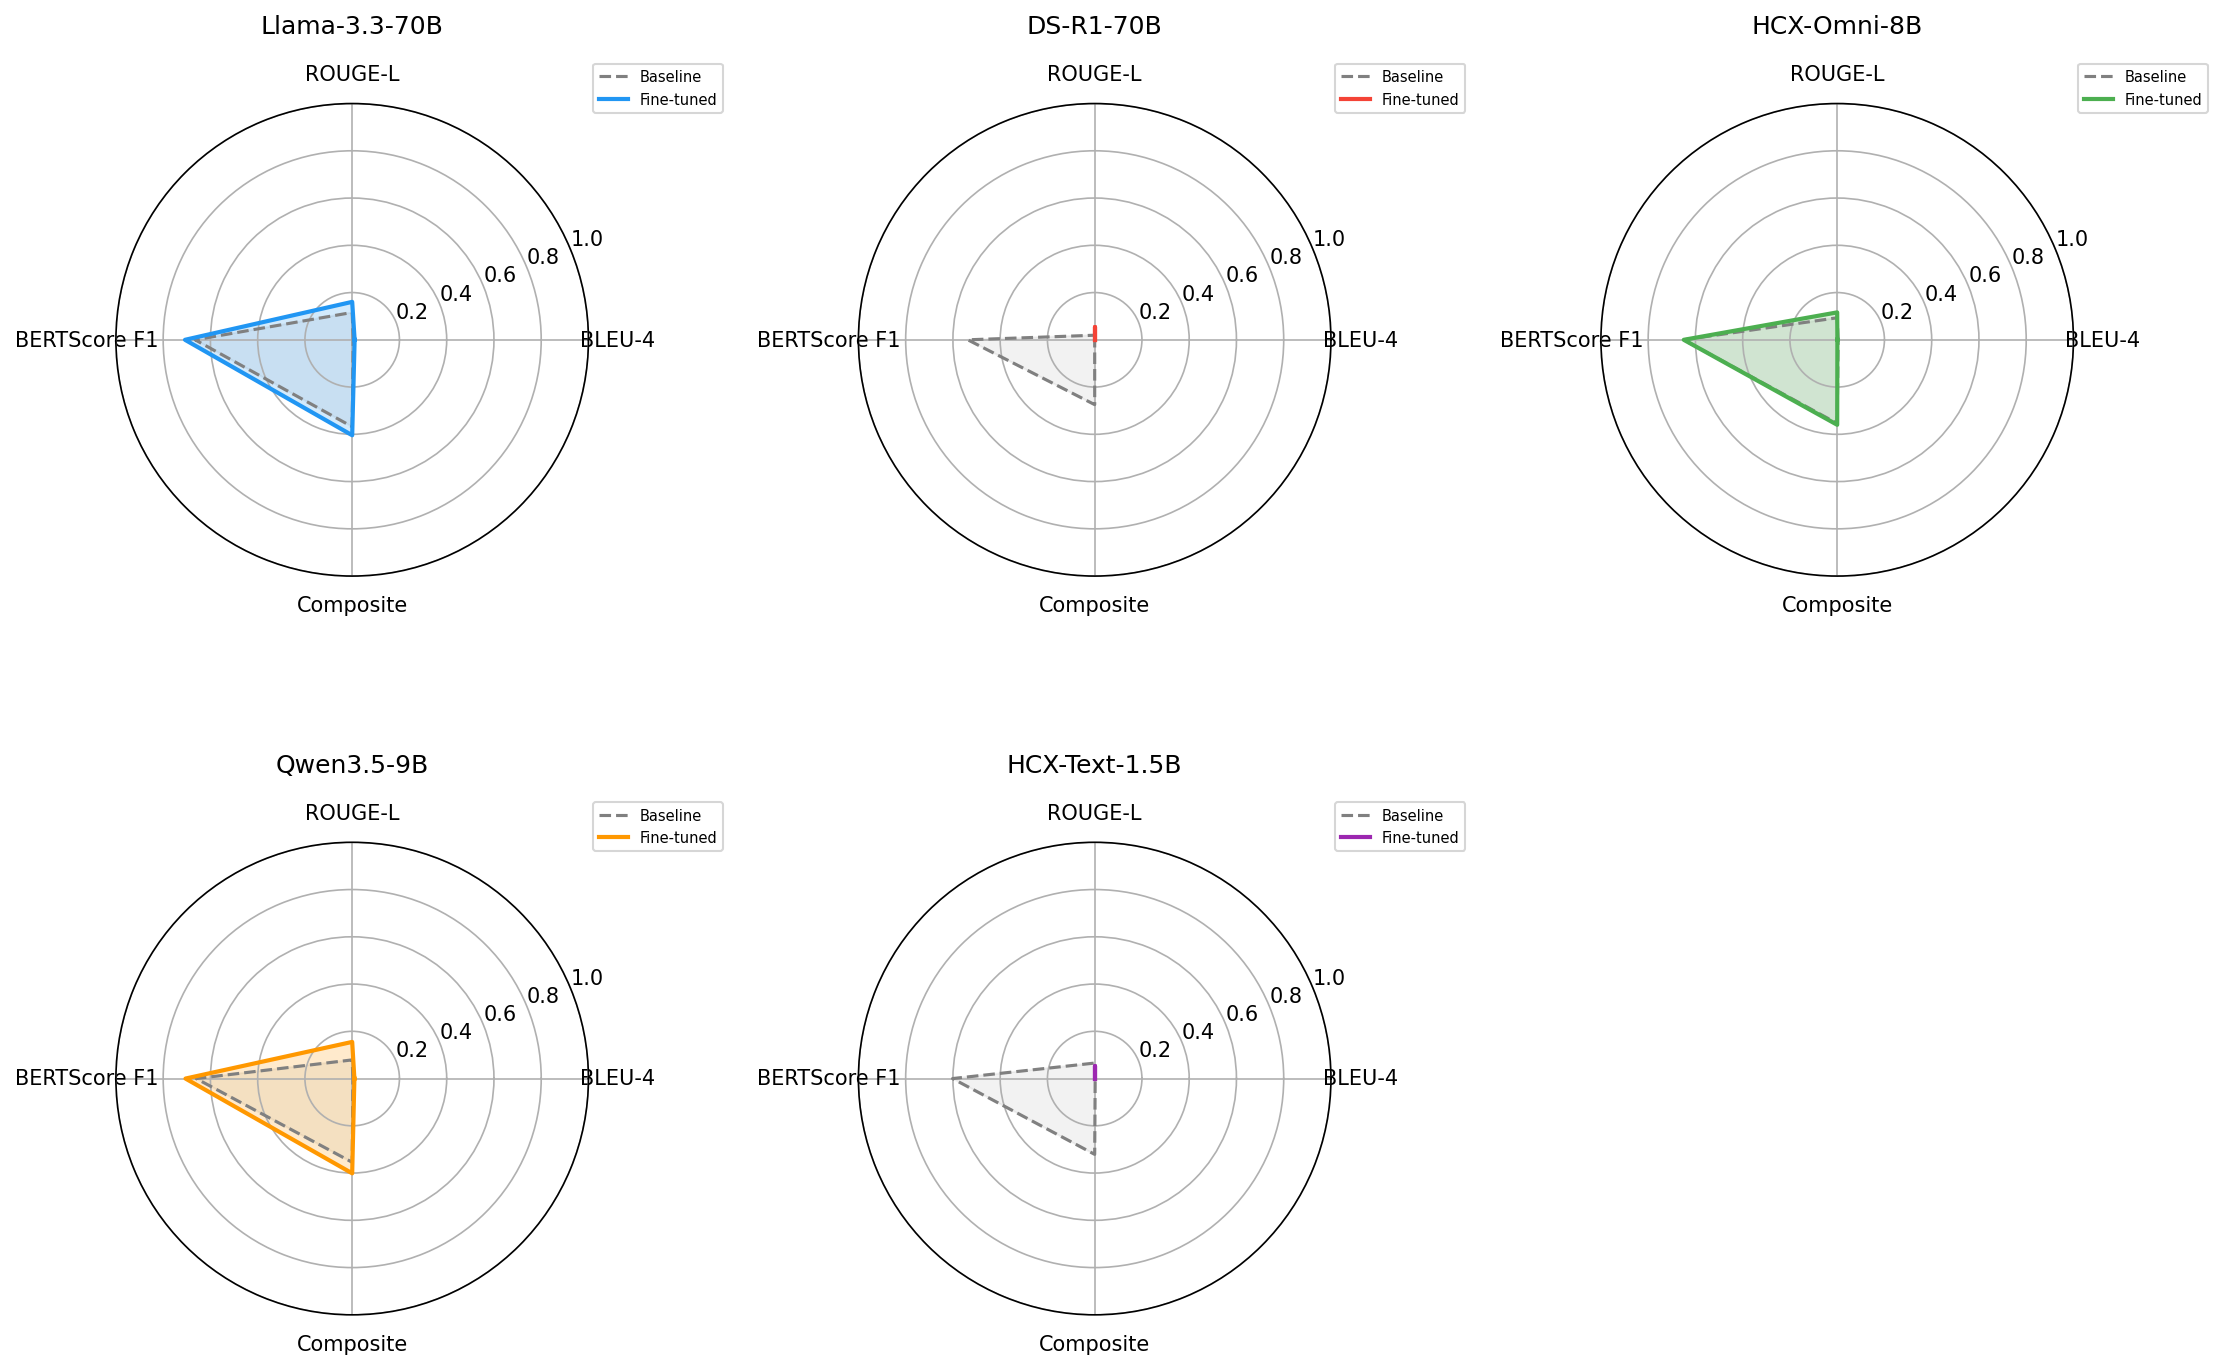
On May 3, having gained enough experience with the 8B models, our team finally challenged the ultimate kings of performance: fine-tuning massive 70B (70 billion parameters) models. We attempted to train both Llama 3.3 70B and DeepSeek-R1 70B, but as expected, we hit a massive hardware resource wall.