[Webots Robotics] Tabular Q-Learning Implementation & Reward Shaping Tuning (#2)
· 5 min read

📌 Key Takeaways (TL;DR)
- Problem: Sparse reward setups (+1.0 at goal, -1.0 at collision) cause severe exploration delays, causing the agent to wander or spin for thousands of episodes before stumbling upon the target.
- Solution: Implemented a multi-objective Dense Reward Shaping mechanism combining potential-based Euclidean distance delta rewards (+0.1 × Δdist) with step (-0.01), turning (-0.01), and backward (-0.05) penalties, paired with exponential epsilon decay (1.0 → 0.05).
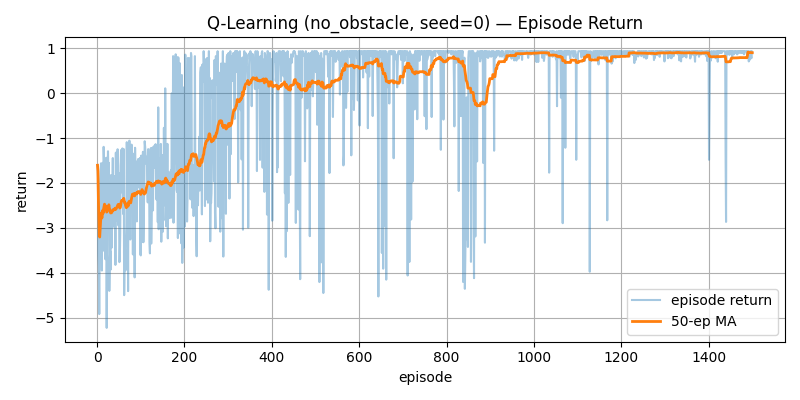
- Result: The moving average reward shifted into a steady positive regime (0.7+) within 500 episodes in the
no_obstaclescenario, achieving a 98%+ goal success rate.