[Stanford CS329A #4] Tool Use & Code Feedback: ReAct, RLEF, and Constitutional Self-Correction

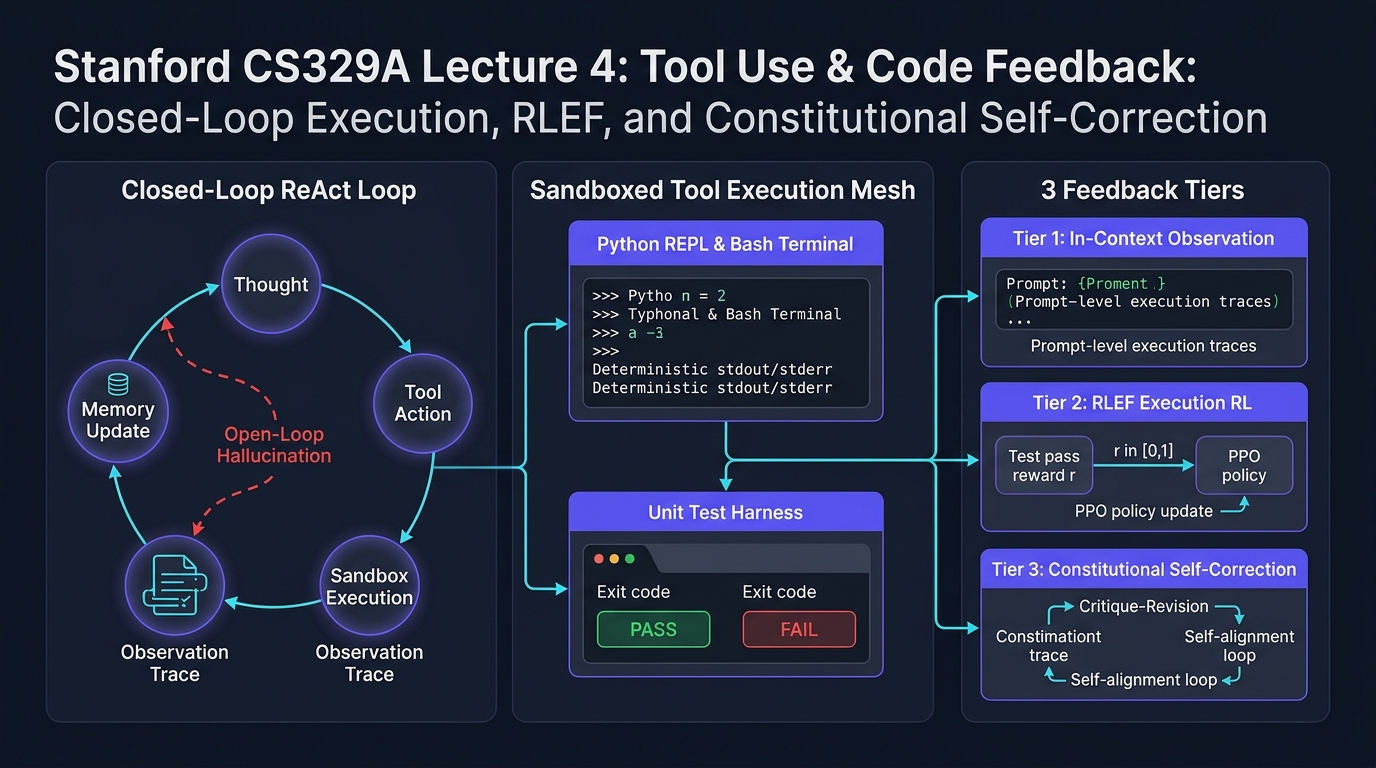
Welcome to the fourth installment of our engineering breakdown of Stanford University's CS329A: Self-Improving AI Agents (Autumn 2025).
In Lectures 2 and 3, we explored how test-time compute scaling and Process Reward Models (PRMs) allow models to explore reasoning trees and verify intermediate mathematical derivations. Yet, despite their sophisticated internal reasoning chains, models constrained to pure text generation remain "closed-room test takers"—entirely dependent on static, frozen parametric memory acquired during pre-training. When faced with evolving external facts, dynamic APIs, or syntax-critical code execution, an ungrounded model inevitably hallucinates, incapable of verifying its outputs against real-world systems.
Today, we break out of that closed room. Lecture 4 marks the structural pivot from passive language models to active, closed-loop autonomous agents: Tool Use and Execution Feedback Loops.
Instead of treating code or API calls as final text generation targets, modern autonomous agents treat tools as interactive sensors and actuators. In this lecture, we dissect the three fundamental tiers of agentic feedback:
- Prompt-Level Environment Feedback: Unifying reasoning and actions via ReAct (Yao et al., 2022).
- Policy-Level Execution Feedback: Baking compiler and test-runner diagnostics directly into neural weights via RLEF (Reinforcement Learning from Execution Feedback, 2024).
- Self-Supervised Value Alignment: Replacing expensive human evaluators with autonomous critique-revision loops via Constitutional AI (Anthropic, 2022).
flowchart TD
    subgraph ClosedLoop ["The Closed-Loop Agent Architecture"]
        direction TB
        Agent["Autonomous Agent Core (LLM)"]
        Thought["Internal Reasoning (Thought Space L)"]
        Action["Executable Tool Call (Action Space A)"]
        Sandbox["Execution Sandbox (Python REPL / Shell / Search)"]
        Obs["Deterministic Environment Observation (Stdout / Stderr)"]

        Agent --> Thought
        Thought --> Action
        Action --> Sandbox
        Sandbox --> Obs
        Obs -->|"Feedback Loop (c_{t+1})"| Agent
    end

    subgraph FeedbackTiers ["The 3 Tiers of Agentic Feedback"]
        direction TB
        T1["Tier 1: In-Context Environment Feedback<br/>• ReAct Loop: Interleaved Thought + Action<br/>• Eliminates Fact Hallucination in Knowledge Retrieval"]
        --> T2["Tier 2: Policy-Level Execution Feedback (RLEF)<br/>• MDP Formulation: State, Action, Sandbox Reward<br/>• PPO Optimization with Public vs Private Test Suites<br/>• Llama-3.1-70B jumps from 27.5% to 40.1% in 1@3 trials"]
        --> T3["Tier 3: Autonomous Value Self-Correction<br/>• Constitutional AI: Natural Language Operational Axioms<br/>• Critique-and-Revision SFT + RLAIF Preference PPO<br/>• Zero Human Annotation Bottleneck"]
    end

    ClosedLoop ==> FeedbackTiers