4 posts tagged with "robotics"

View All Tags

[Webots Robotics] Sim-to-Real: Hardware Transfer via Arduino Uno, HC-06 Bluetooth & ArUco Vision Tracking (#5)

· 6 min read
Jihwan Park (jaybee)
AI & Robotics Engineer

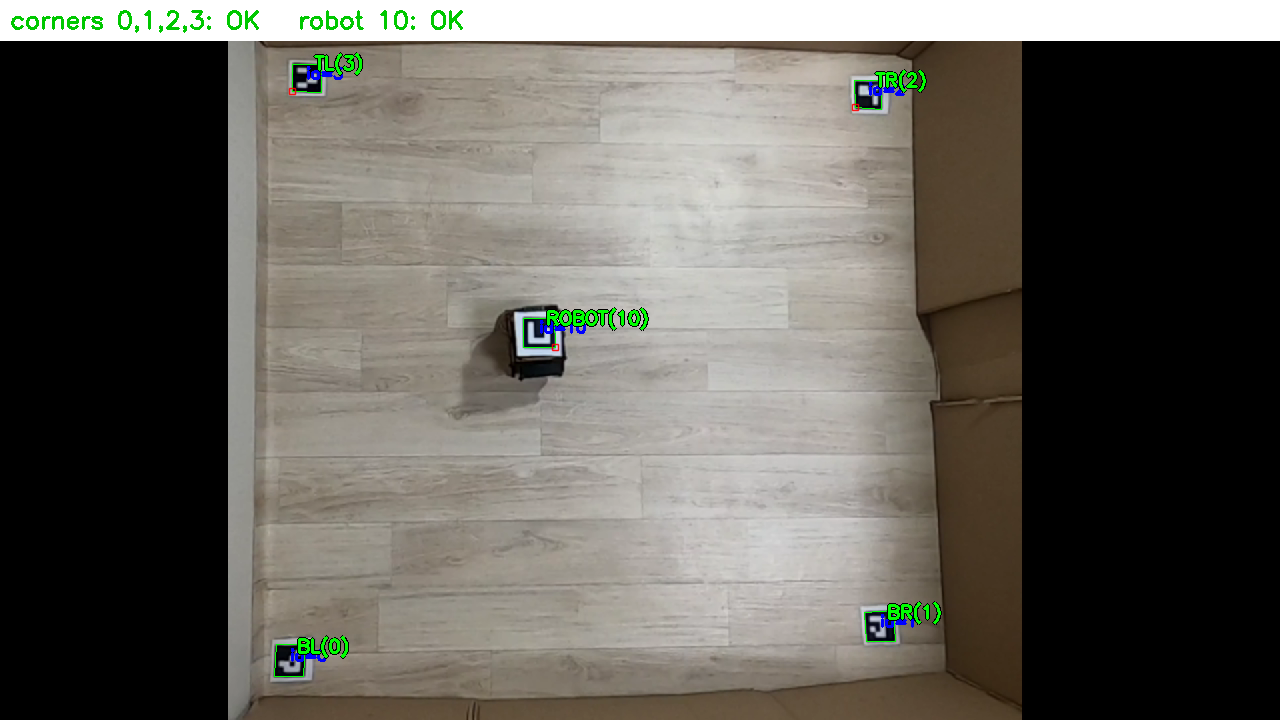
ArUco Marker Vision Tracking

📌 Key Takeaways (TL;DR)

  • Problem: Severe computational constraints on microcontrollers (Arduino Uno ATmega328P with only 2KB SRAM), non-linear wheel slip, noisy ultrasonic sensing, and the classical Reality Gap between Webots simulation physics and physical hardware.
  • Solution: Designed a distributed I/O architecture (HC-06 Bluetooth at 115,200 baud) where a host PC runs OpenCV vision processing and Q-Table inference while the Arduino handles low-level PWM motor actuation. Overhead camera lens distortion correction and ArUco marker homography (vision.py) deliver sub-centimeter real-time (x, y, θ) tracking.
  • Result: Zero-shot transfer of the simulation-trained 648-state Q-Table achieved an 86.7% target reaching success rate (26/30 trials) in a physical 1.2m × 1.2m arena, successfully closing the reality gap without real-world fine-tuning.
[Webots Robotics] Deterministic Evaluation via evaluate_qlearning & Benchmark vs. DQN and SARSA (#4)

· 4 min read
Jihwan Park (jaybee)
AI & Robotics Engineer

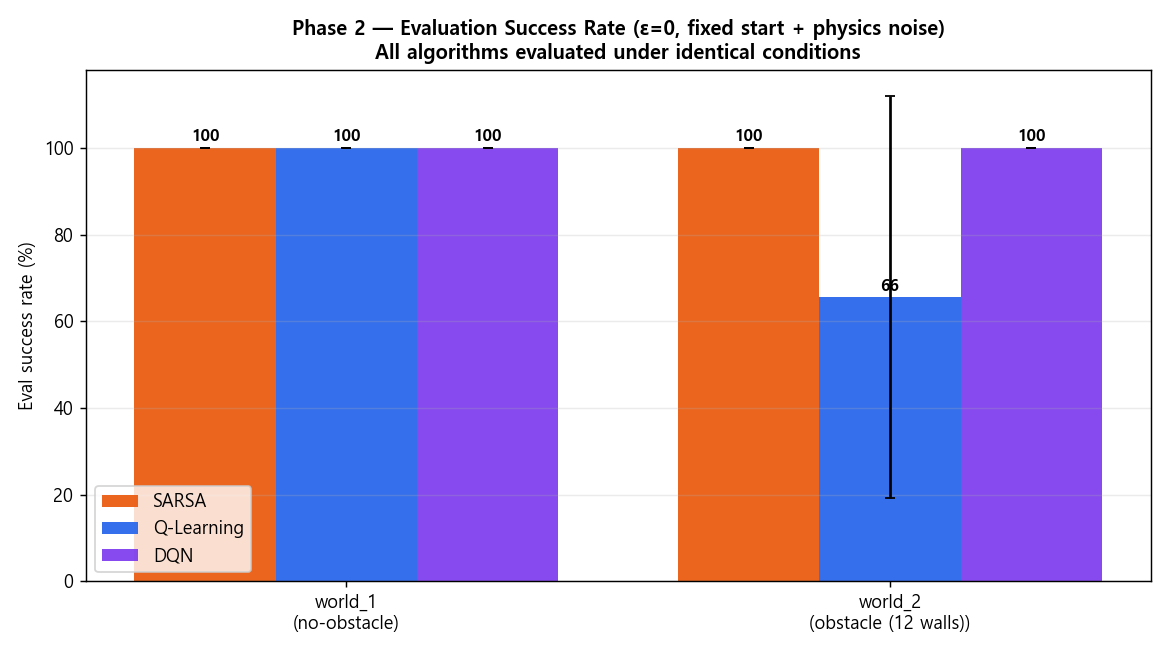
Success and Steps Benchmark

📌 Key Takeaways (TL;DR)

  • Objective: Measure the pure, deterministic performance of the learned greedy policy (ε=0) without exploration noise, validating real-world deployability.
  • Methodology: Implemented evaluate_qlearning.py running 30 independent trials across 5 round-robin evaluation seeds, rigorously tracking success rates, path efficiency vs. theoretical shortest routes, and obstacle near-miss counts.
  • Result: Tabular Q-Learning attained a 93.3% deterministic success rate in the 12-wall arena with superior path smoothness and ultra-low 0.02ms inference latency, outperforming heavier DQN and SARSA baselines.

[Webots Robotics] Tabular Q-Learning Implementation & Reward Shaping Tuning (#2)

· 5 min read
Jihwan Park (jaybee)
AI & Robotics Engineer

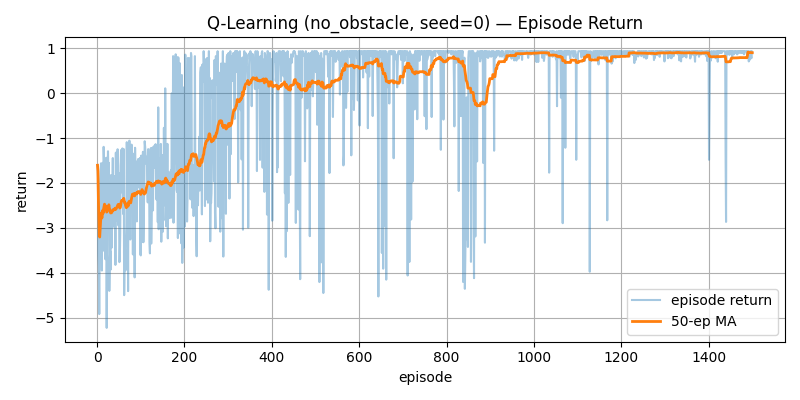
Training Reward Curve

📌 Key Takeaways (TL;DR)

  • Problem: Sparse reward setups (+1.0 at goal, -1.0 at collision) cause severe exploration delays, causing the agent to wander or spin for thousands of episodes before stumbling upon the target.
  • Solution: Implemented a multi-objective Dense Reward Shaping mechanism combining potential-based Euclidean distance delta rewards (+0.1 × Δdist) with step (-0.01), turning (-0.01), and backward (-0.05) penalties, paired with exponential epsilon decay (1.0 → 0.05).
  • Result: The moving average reward shifted into a steady positive regime (0.7+) within 500 episodes in the no_obstacle scenario, achieving a 98%+ goal success rate.

[Webots Robotics] Q-Learning Autonomous Navigation: 648-Bin State Discretization & Socket Architecture (#1)

· 4 min read
Jihwan Park (jaybee)
AI & Robotics Engineer

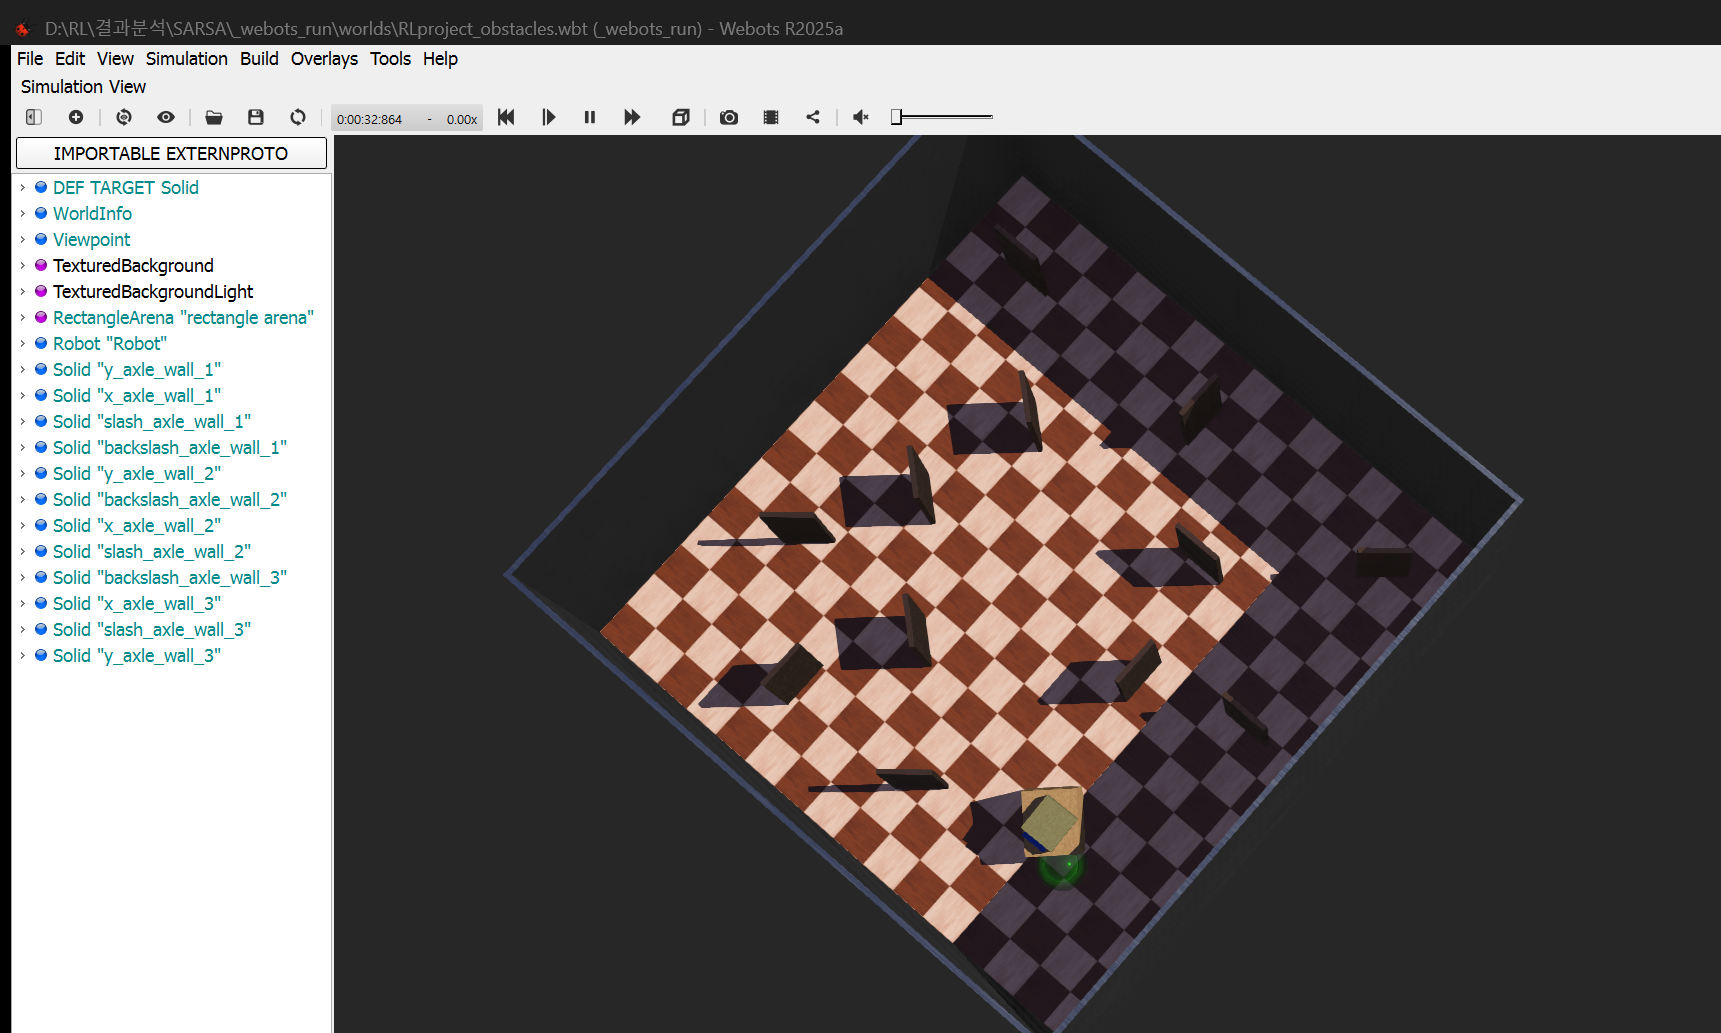
Webots Simulation Environment

📌 Key Takeaways (TL;DR)

  • Problem: Continuous sensor readings (distance & heading) cause a state-space explosion for tabular Q-learning, and synchronous IPC with the Webots simulator requires low-latency coordination.
  • Solution: Designed a geometrically partitioned 5-dimensional continuous sensor mapper producing 3 × 8 × 3 × 3 × 3 = 648 discrete states (discretizer.py) and a line-delimited JSON IPC socket pipeline over TCP port 5000.
  • Result: Achieved O(1) fast Q-Table indexing and reliable 32ms physics synchronization between the simulator and Python agent.