[Journal de bord Maeumjigi Capstone #12] Fine-tuning du modèle géant 70B & Défi de la mémoire GPU (OOM)
· 3 minutes de lecture

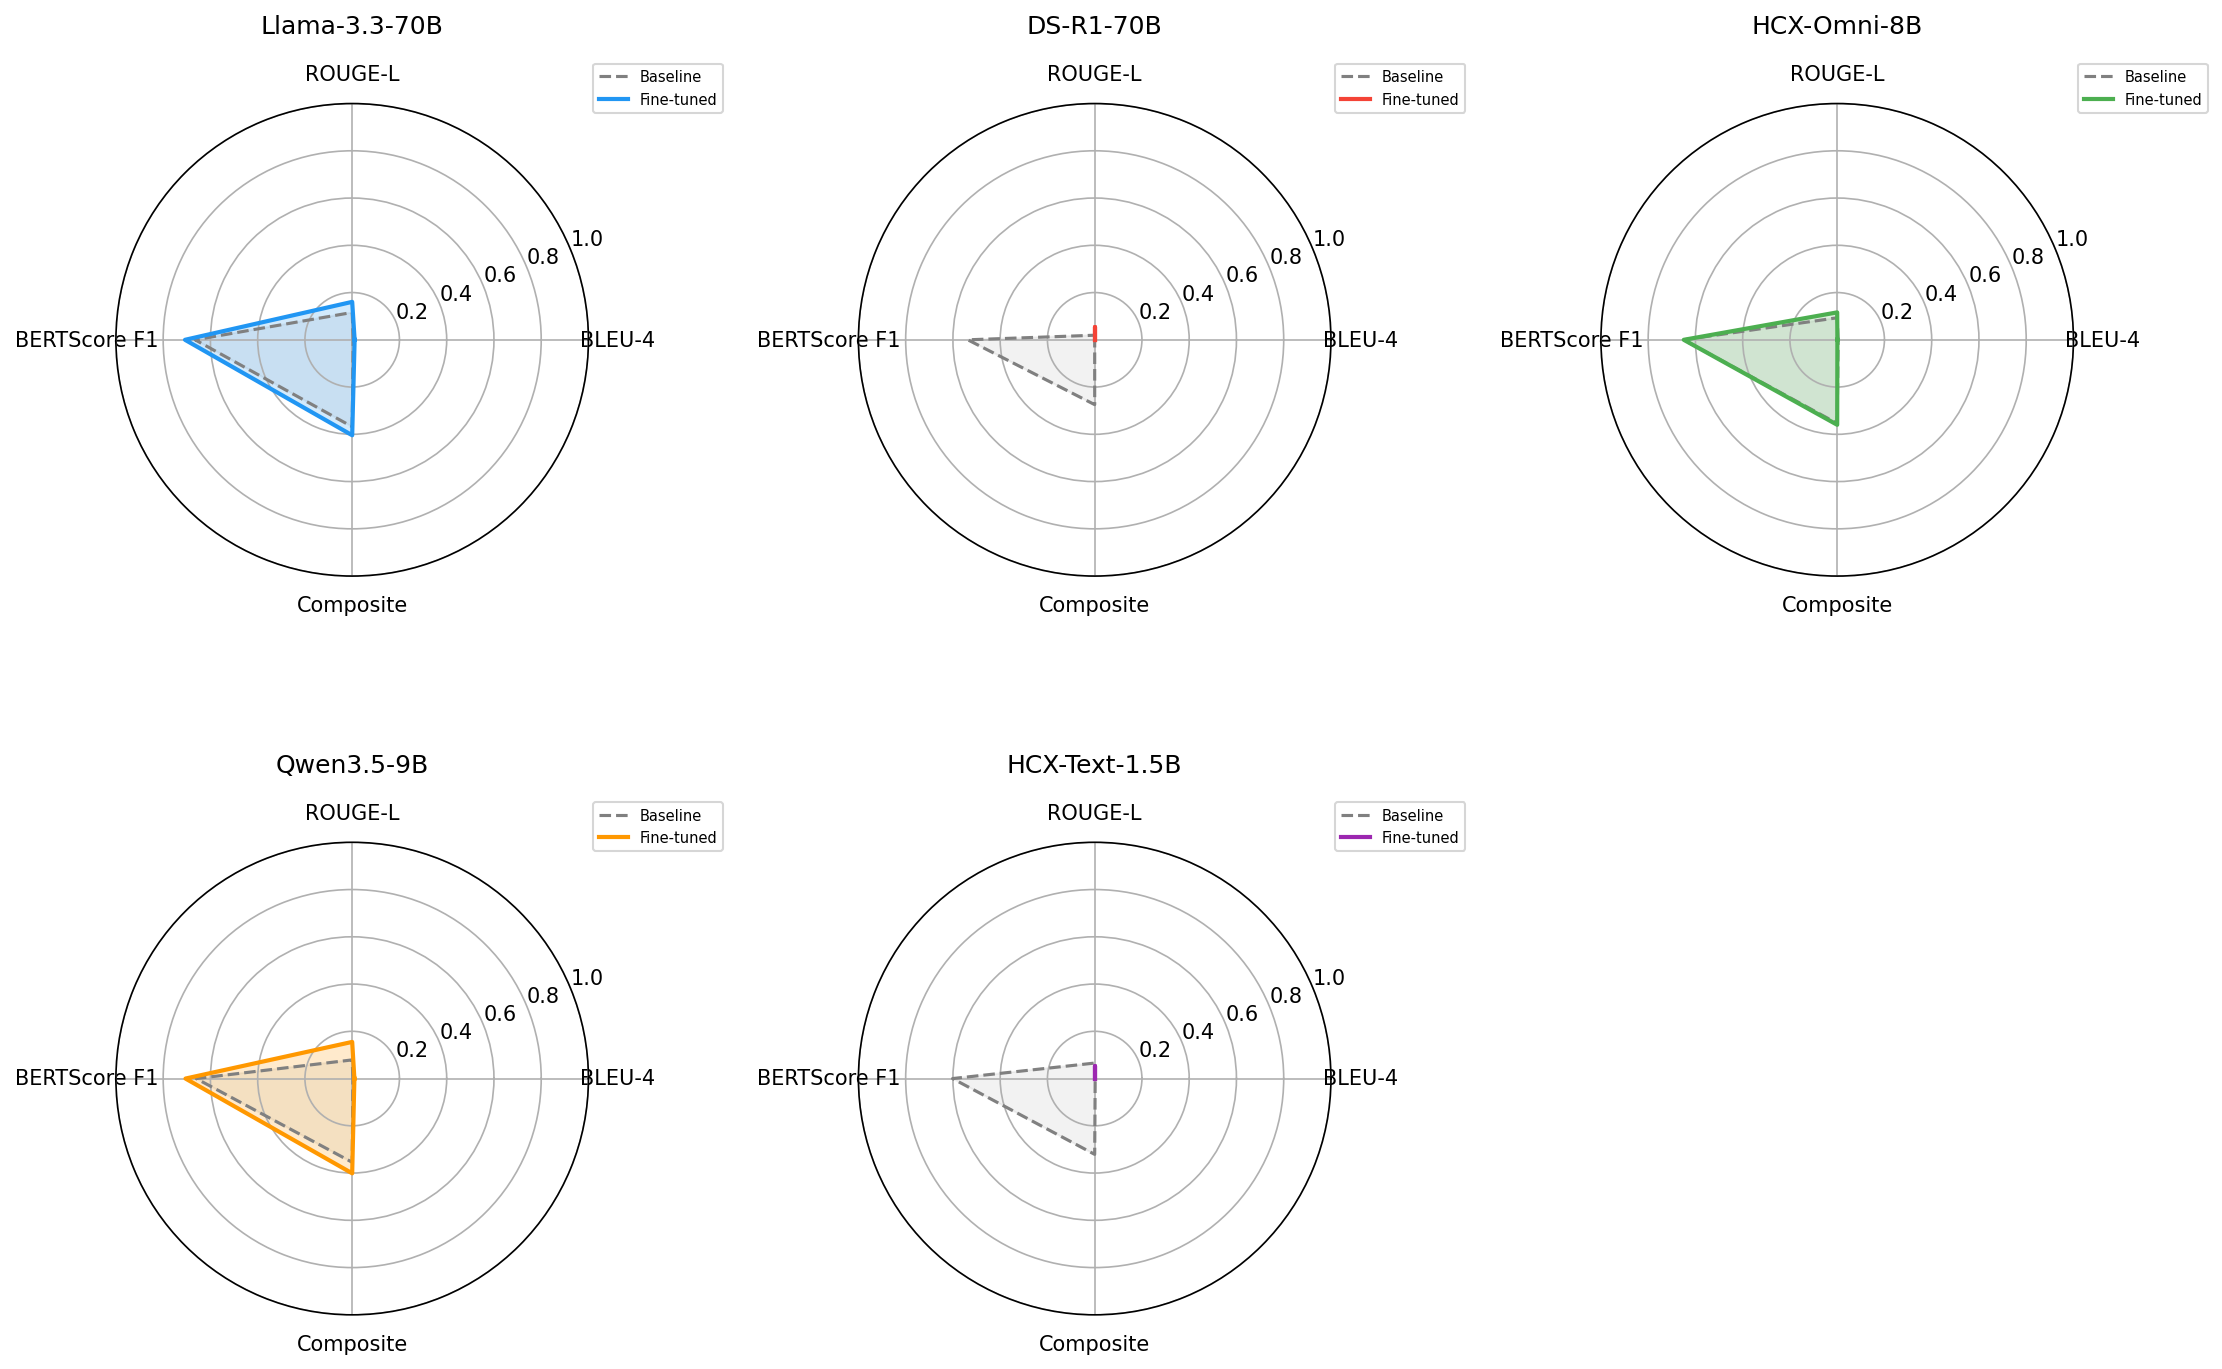
On May 3, having gained enough experience with the 8B models, our team finally challenged the ultimate kings of performance: fine-tuning massive 70B (70 billion parameters) models. We attempted to train both Llama 3.3 70B and DeepSeek-R1 70B, but as expected, we hit a massive hardware resource wall.