[マウムジギ Capstone 開発日誌 #4] 本格データ前処理: Llama 3.1 チャットテンプレートと自律型 JSONL パイプライン
· 約4分

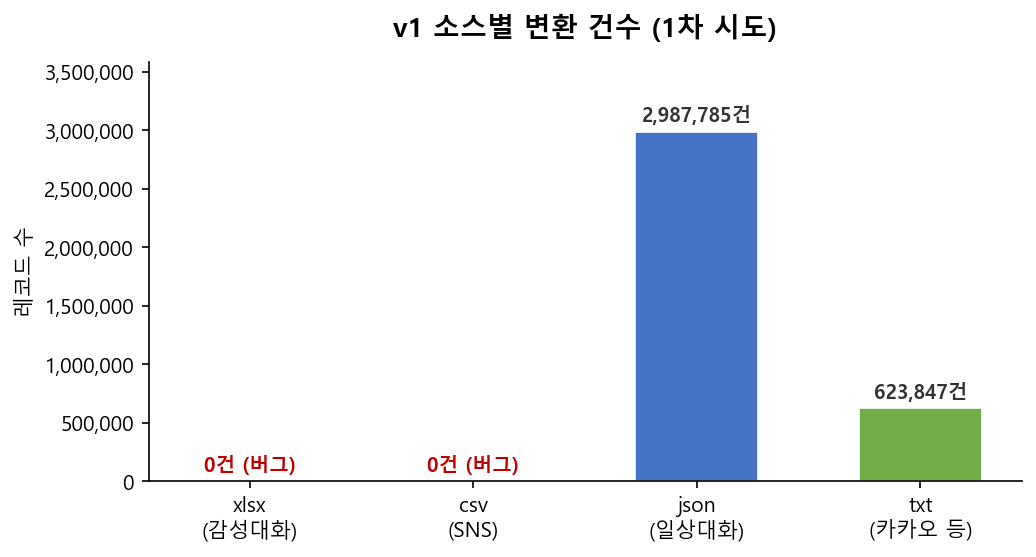
April 1, 2026, was the day our engineering team launched the automated preprocessing pipeline for the massive counseling corpora that would form the foundation of Maeumjigi. Training a high-performance open-source Large Language Model (LLM) like Meta Llama 3.1 requires rigorous data hygiene: converting unstructured multi-party dialogues into clean, token-bounded, and special-token-aligned instruction datasets.