[Diário de Bordo Maeumjigi Capstone #13] Limites do Treinamento de 70B & Pivot para Modelos Médios (HCX, Qwen 2.5)
· 3 min para ler

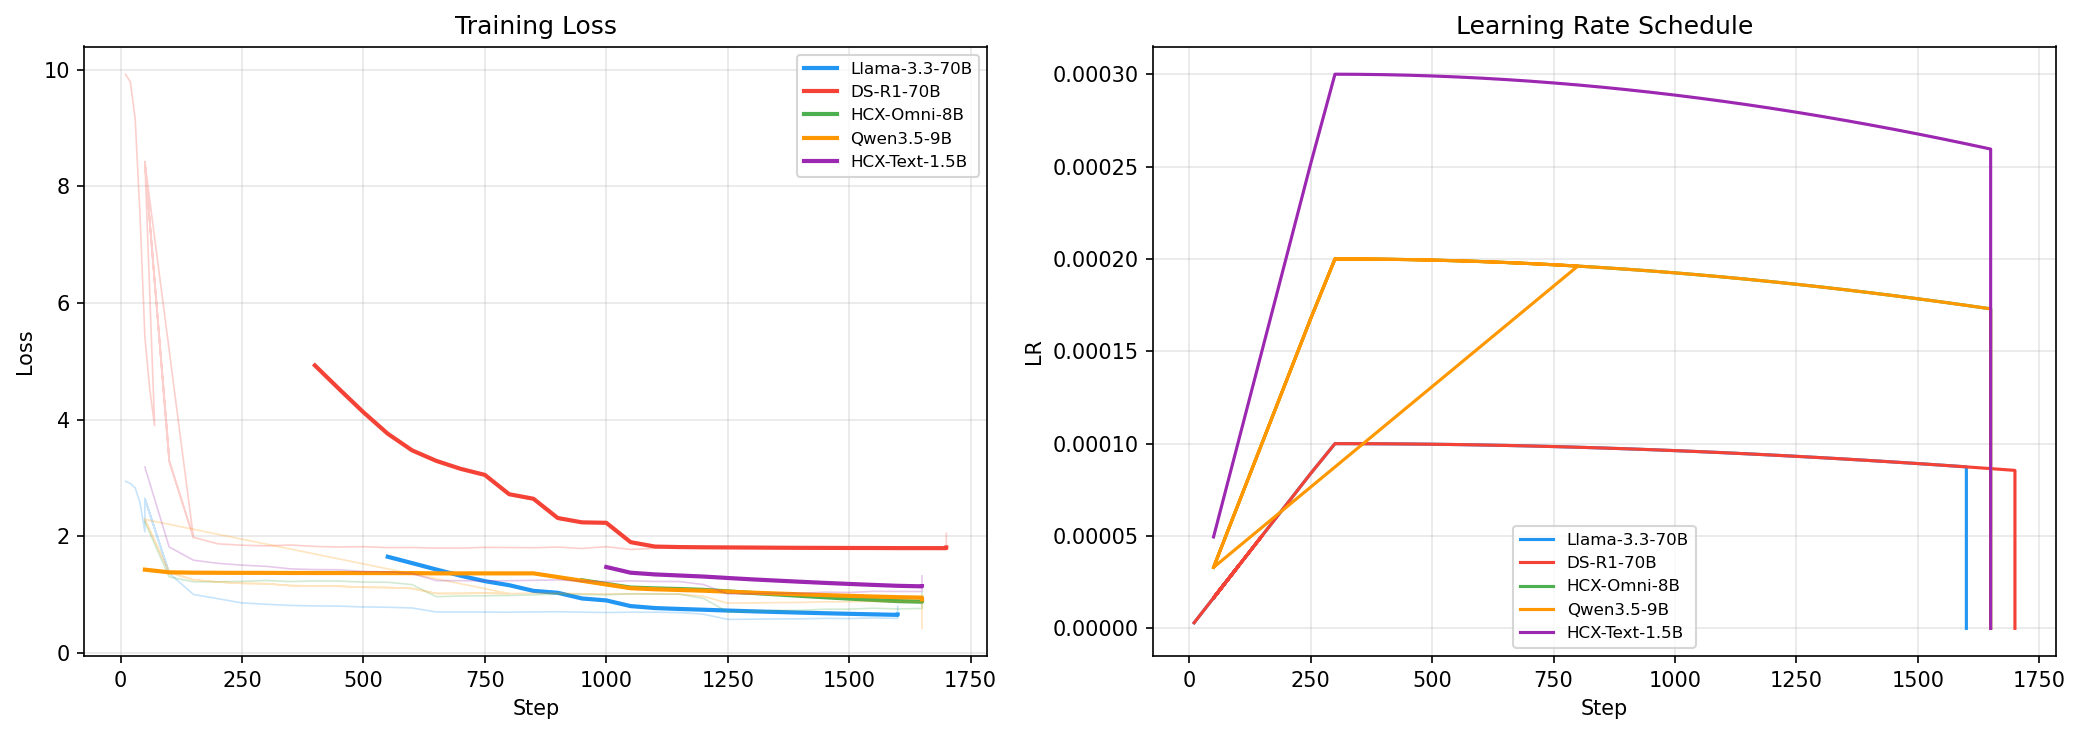
After experiencing the OOM (Out of Memory) hell during the fine-tuning of massive 70B models, on May 4th, we attempted a bold change in strategy. By drastically reducing the batch size, we barely managed to push the 70B models (Llama3.3, DeepSeek-R1) to checkpoint-1200 and 1300, but the training time was absurdly long, resulting in terrible efficiency.