Pular para o conteúdo principal

13 publicações com a etiqueta "fine-tuning"

Ver todas as etiquetas

[Diário de Bordo Maeumjigi Capstone #22] O Triunfo da 4ª Rodada: Checkpoint-4400, Proporções de Dados & Arquitetura Global

· 5 min para ler
Jaybee
AI & Robotics Engineer

Cover Image

The final week of May 2026 (May 27–30) proved to be the grand culmination of our experimental modeling phase. After weeks of hyperparameter tuning, GPU out-of-memory crashes, and dataset revisions, our 4th Fine-Tuning cycle (fine_tuning_4) crossed the finish line.

This post reveals the technical breakthrough that resolved the chronic "over-counseling" trap, quantitative validation of our golden weight Checkpoint-4400, and the end-to-end system architecture designed for real-world deployment.
[Diário de Bordo Maeumjigi Capstone #15] Visualização dos Resultados de 5 Modelos & Configuração do Ambiente Local

· 3 min para ler
Jaybee
AI & Robotics Engineer

Cover Image

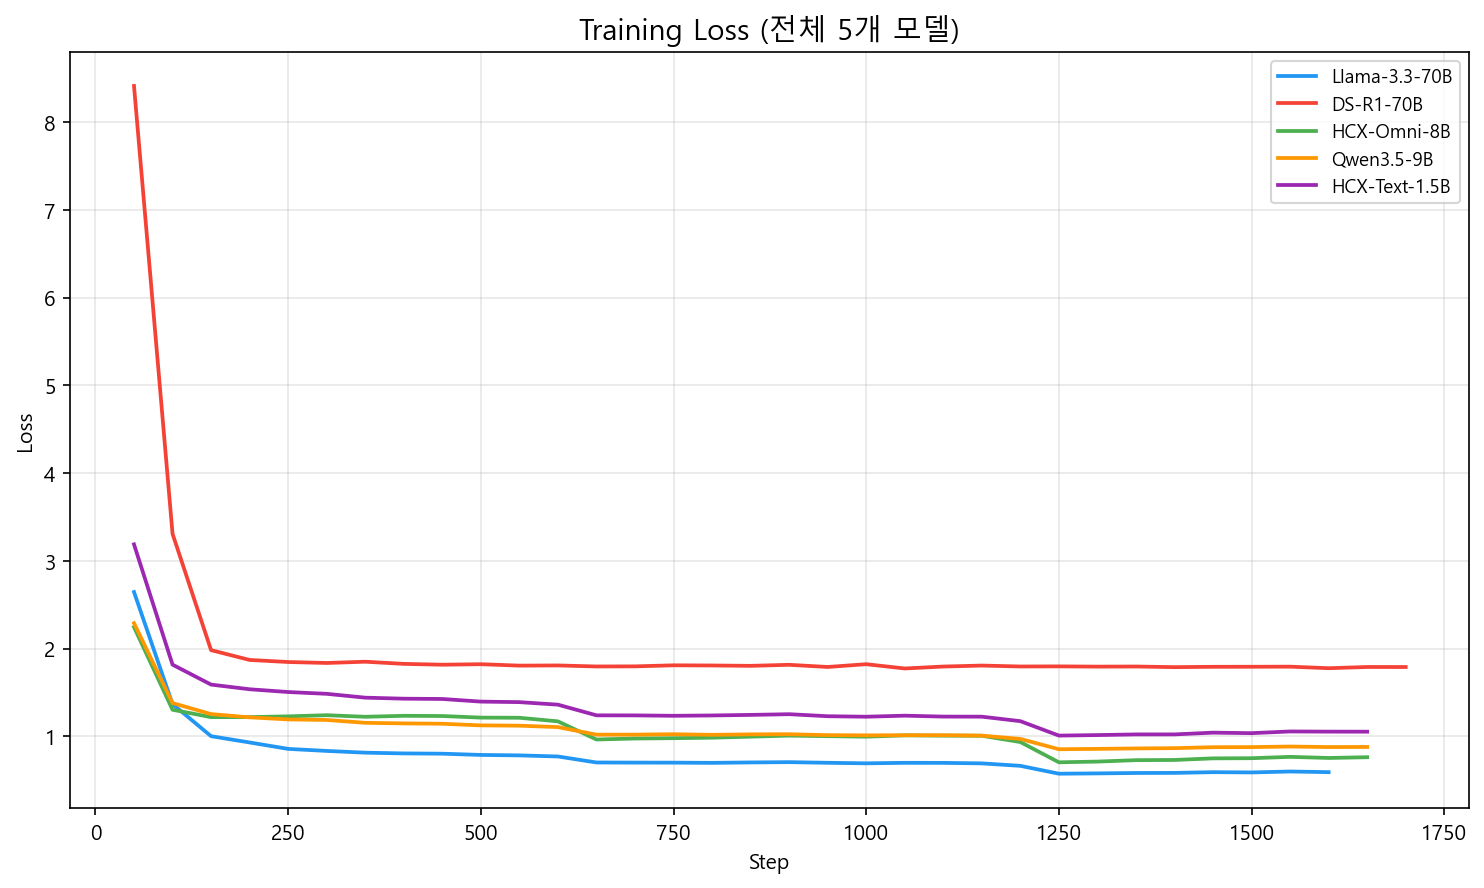
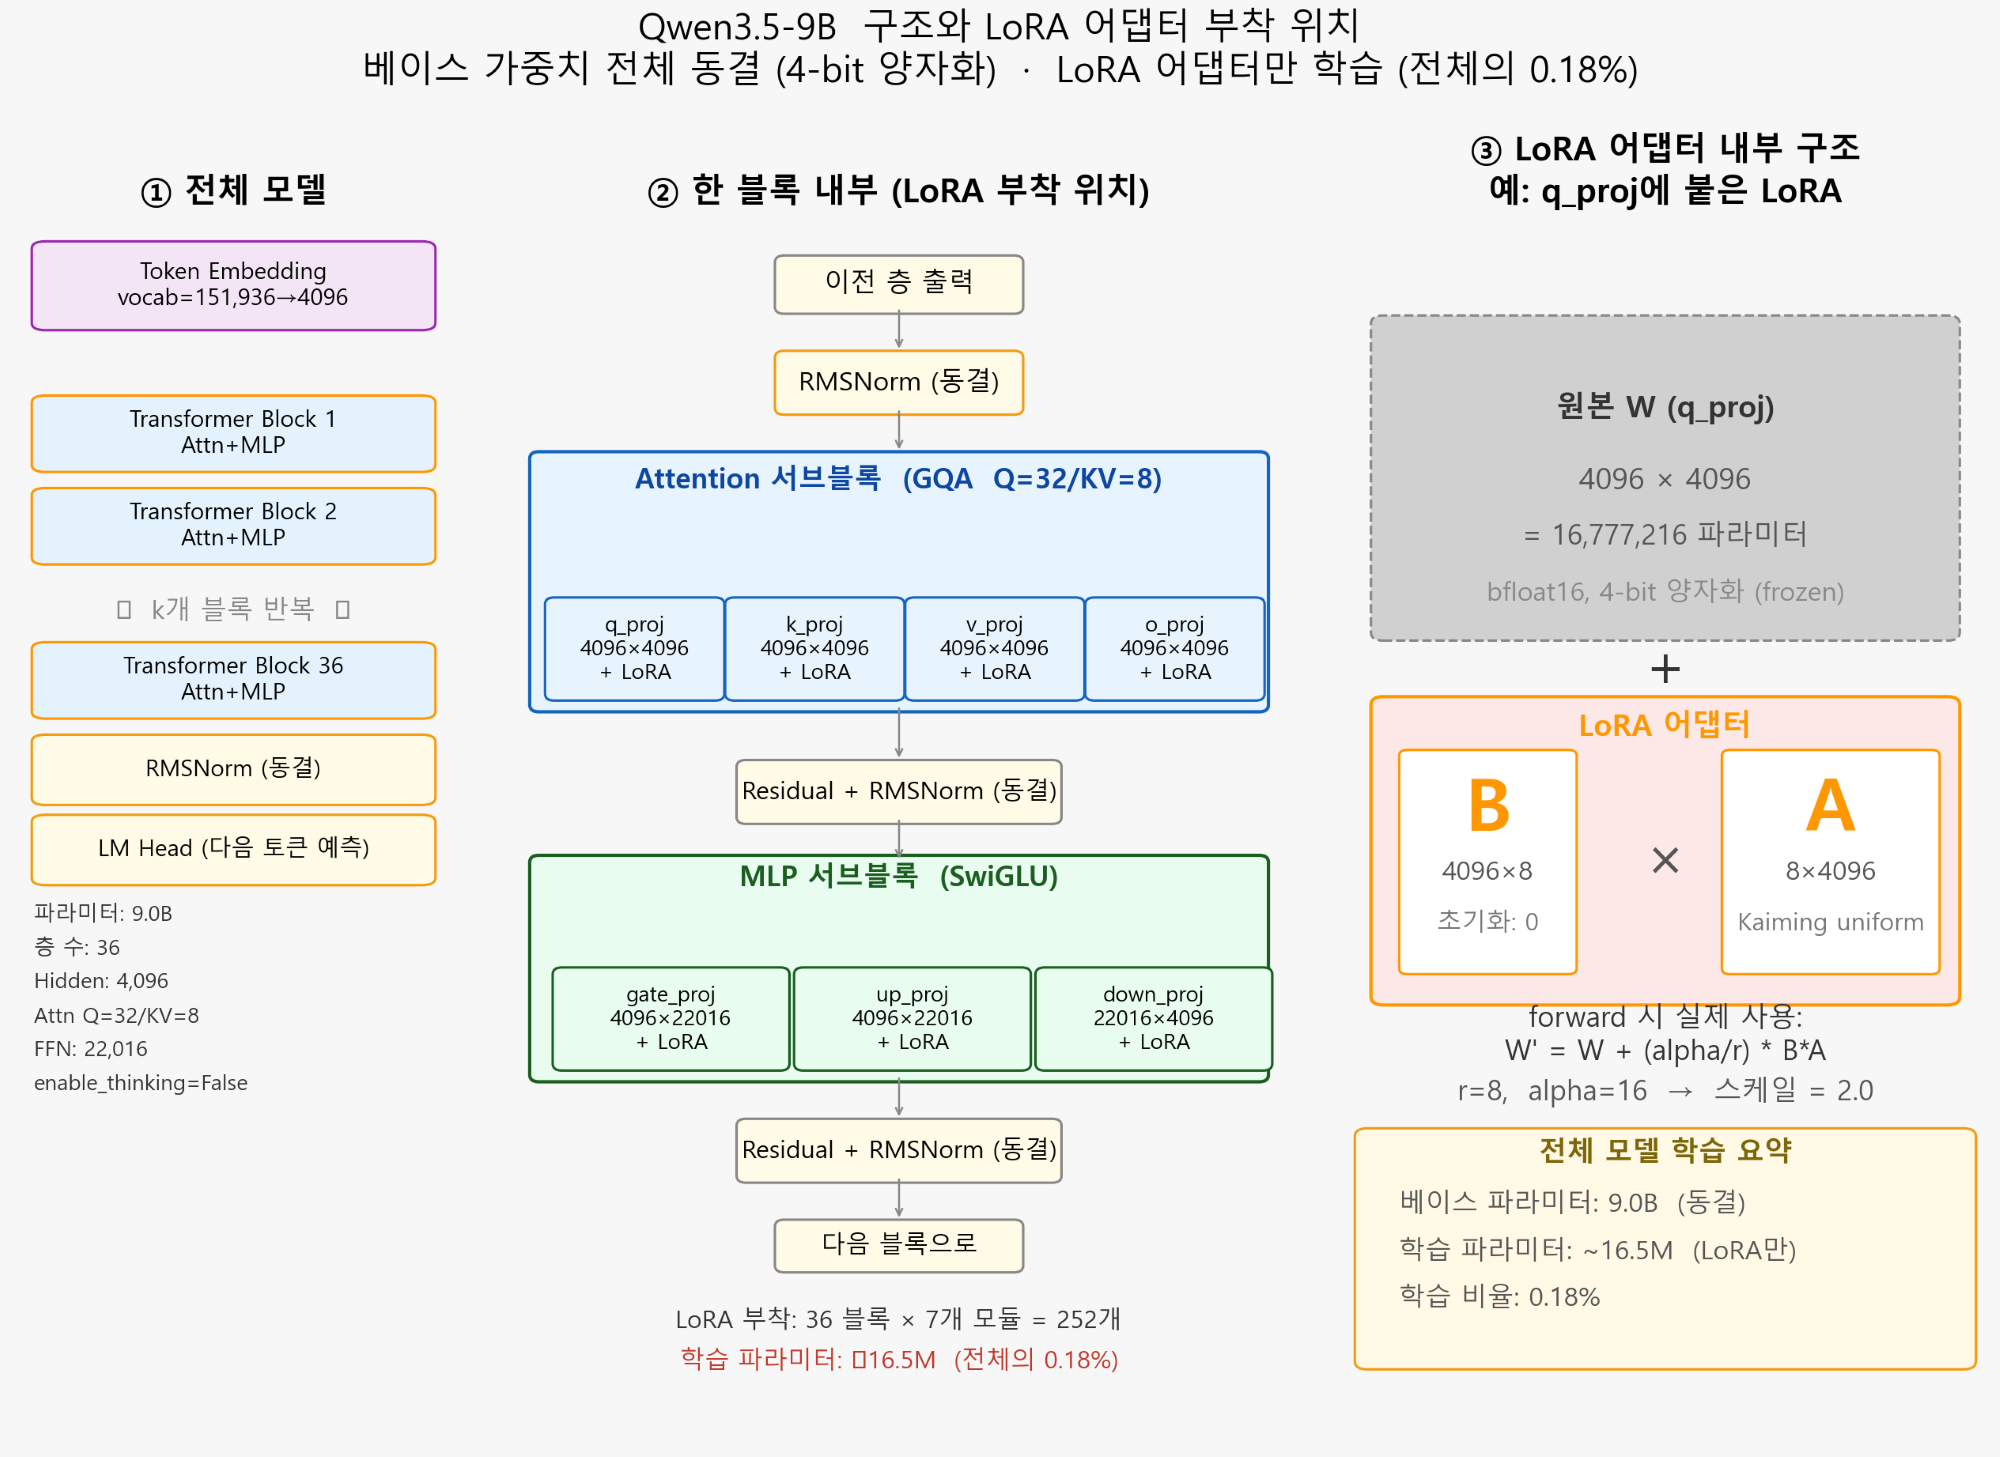
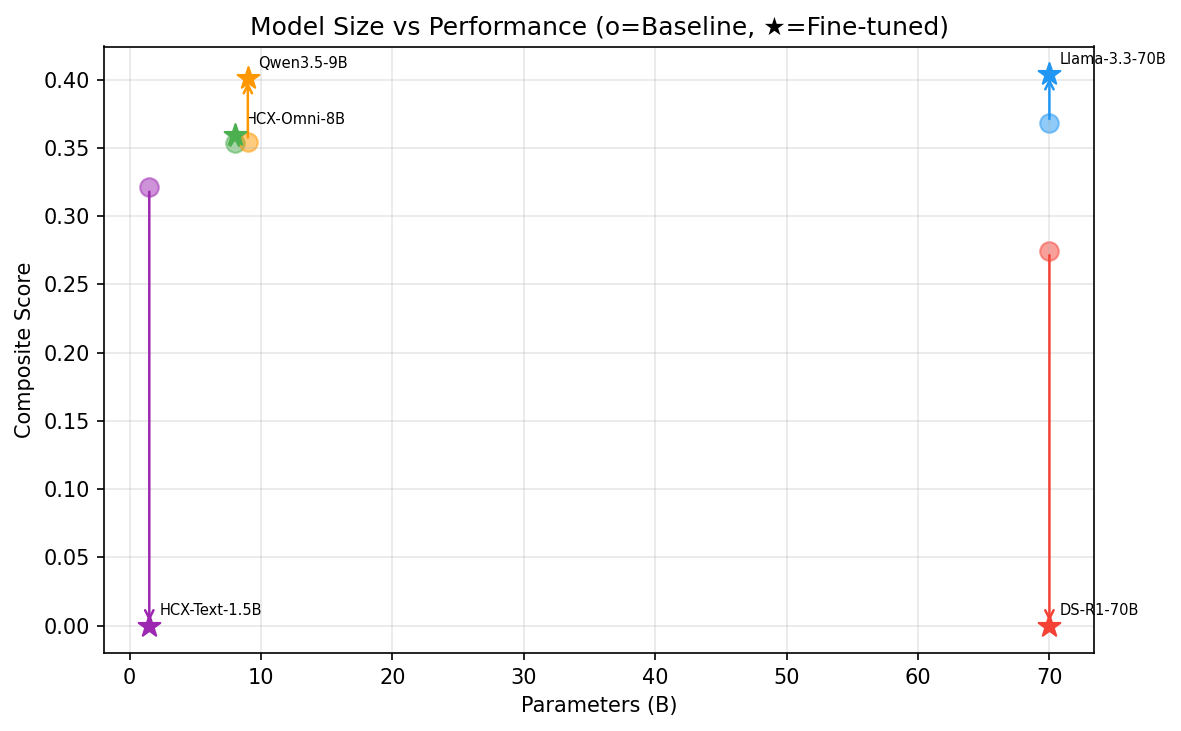
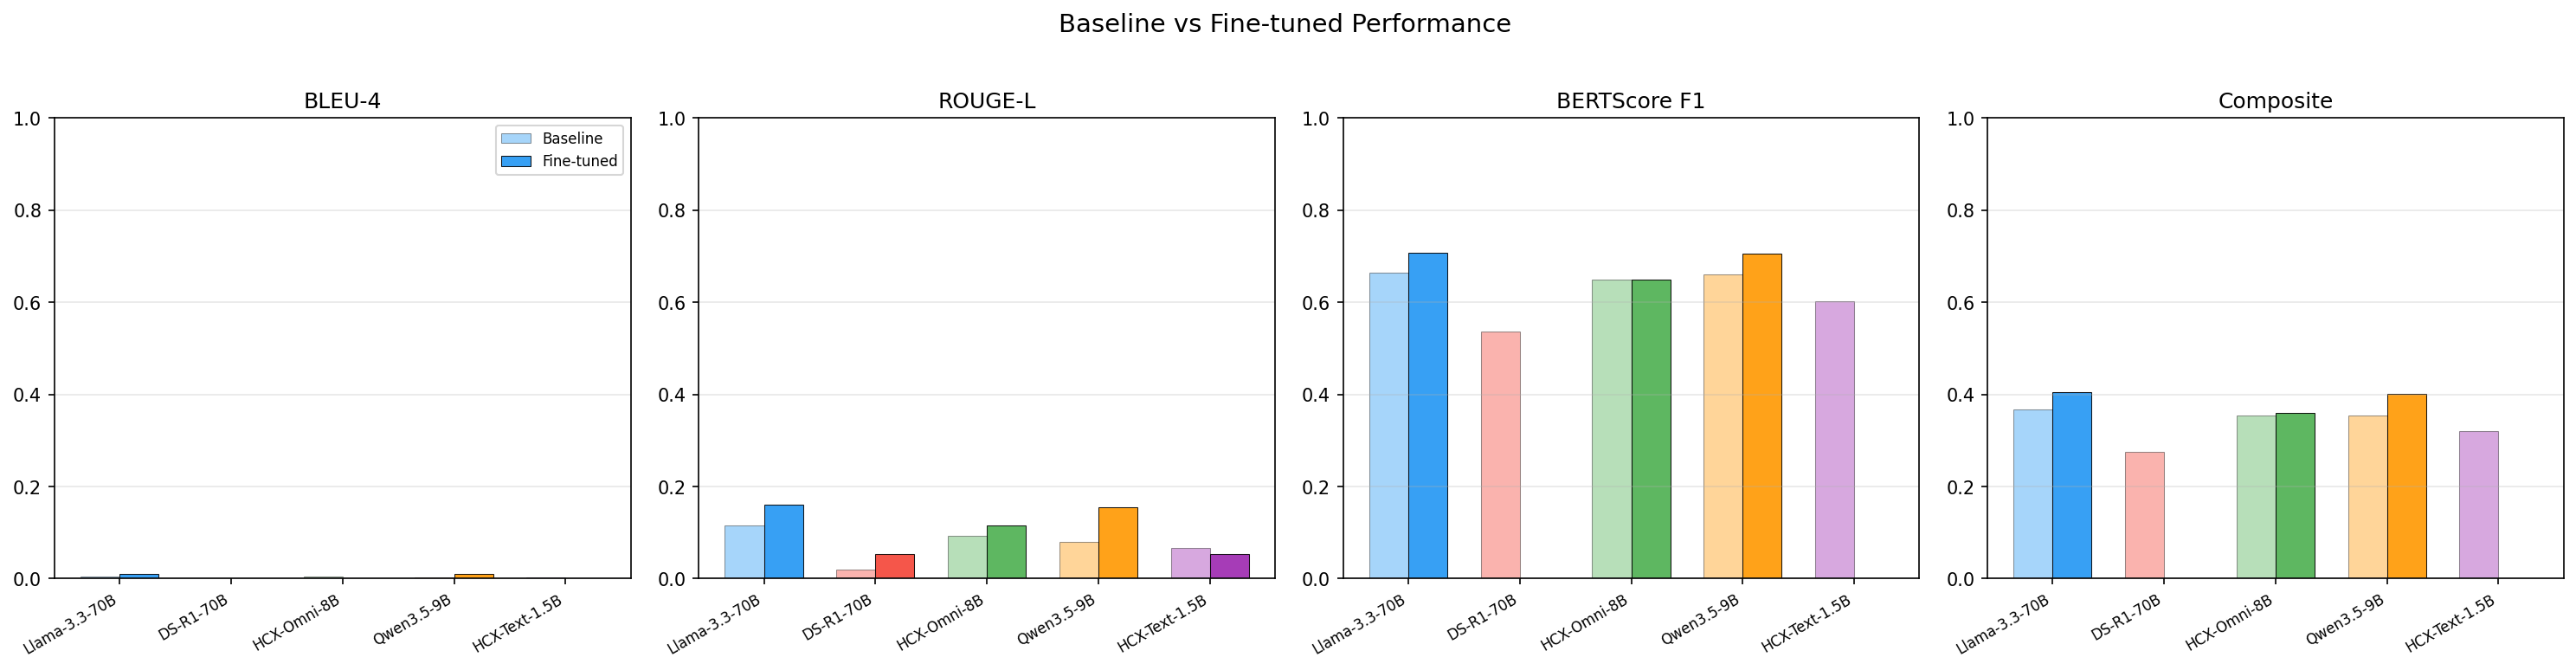
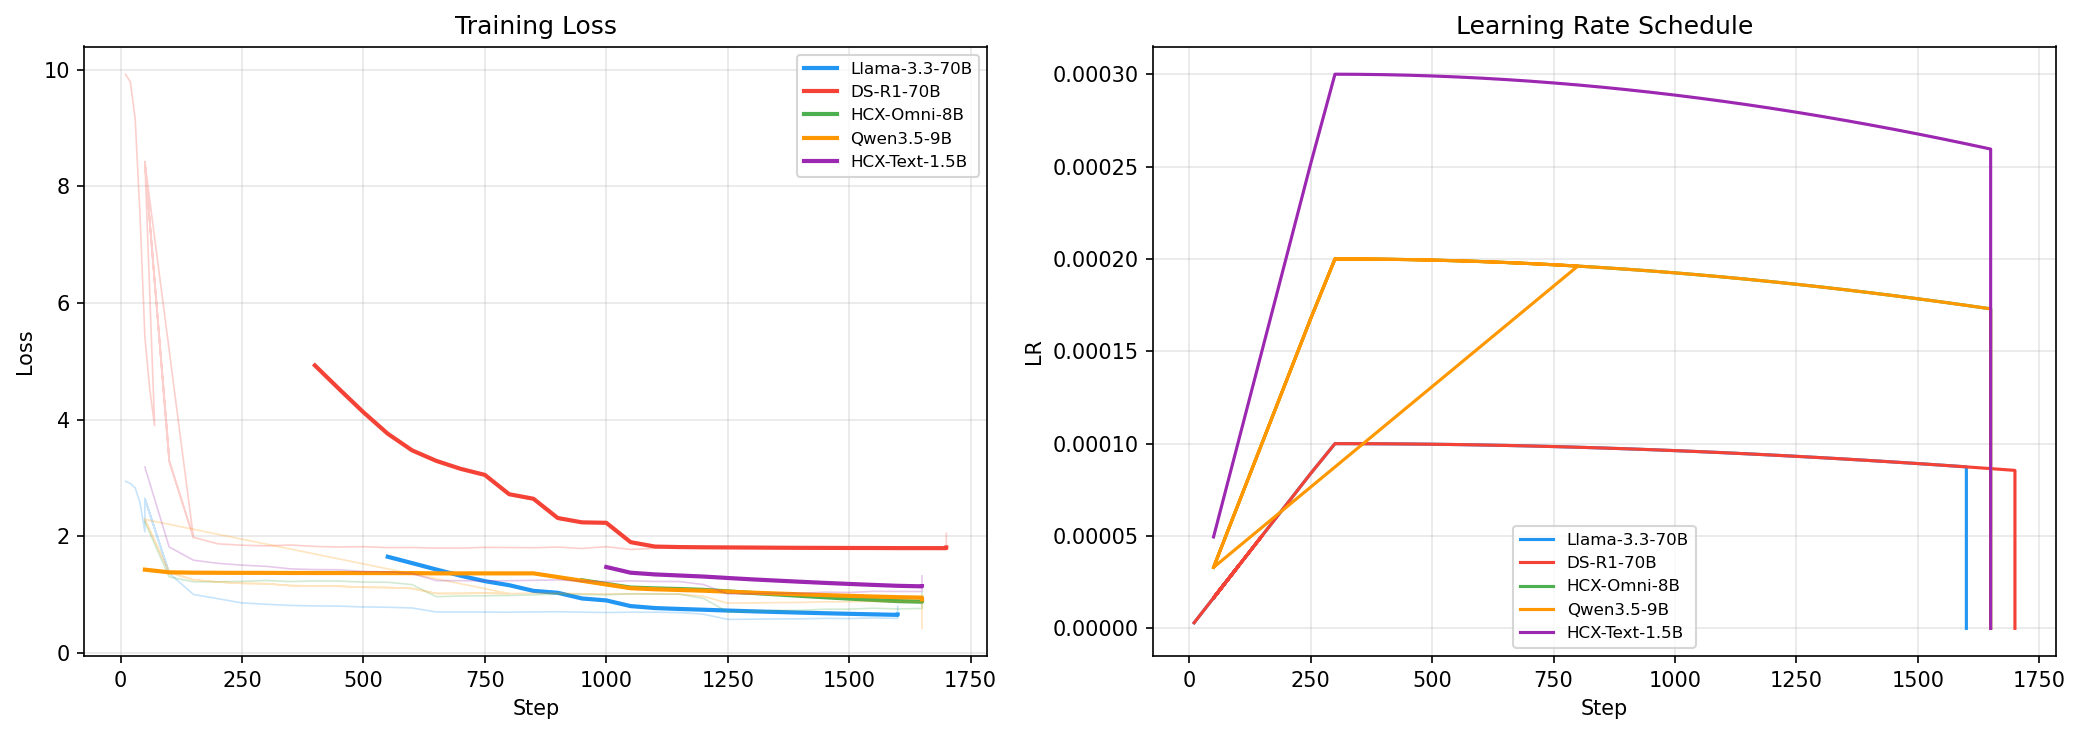
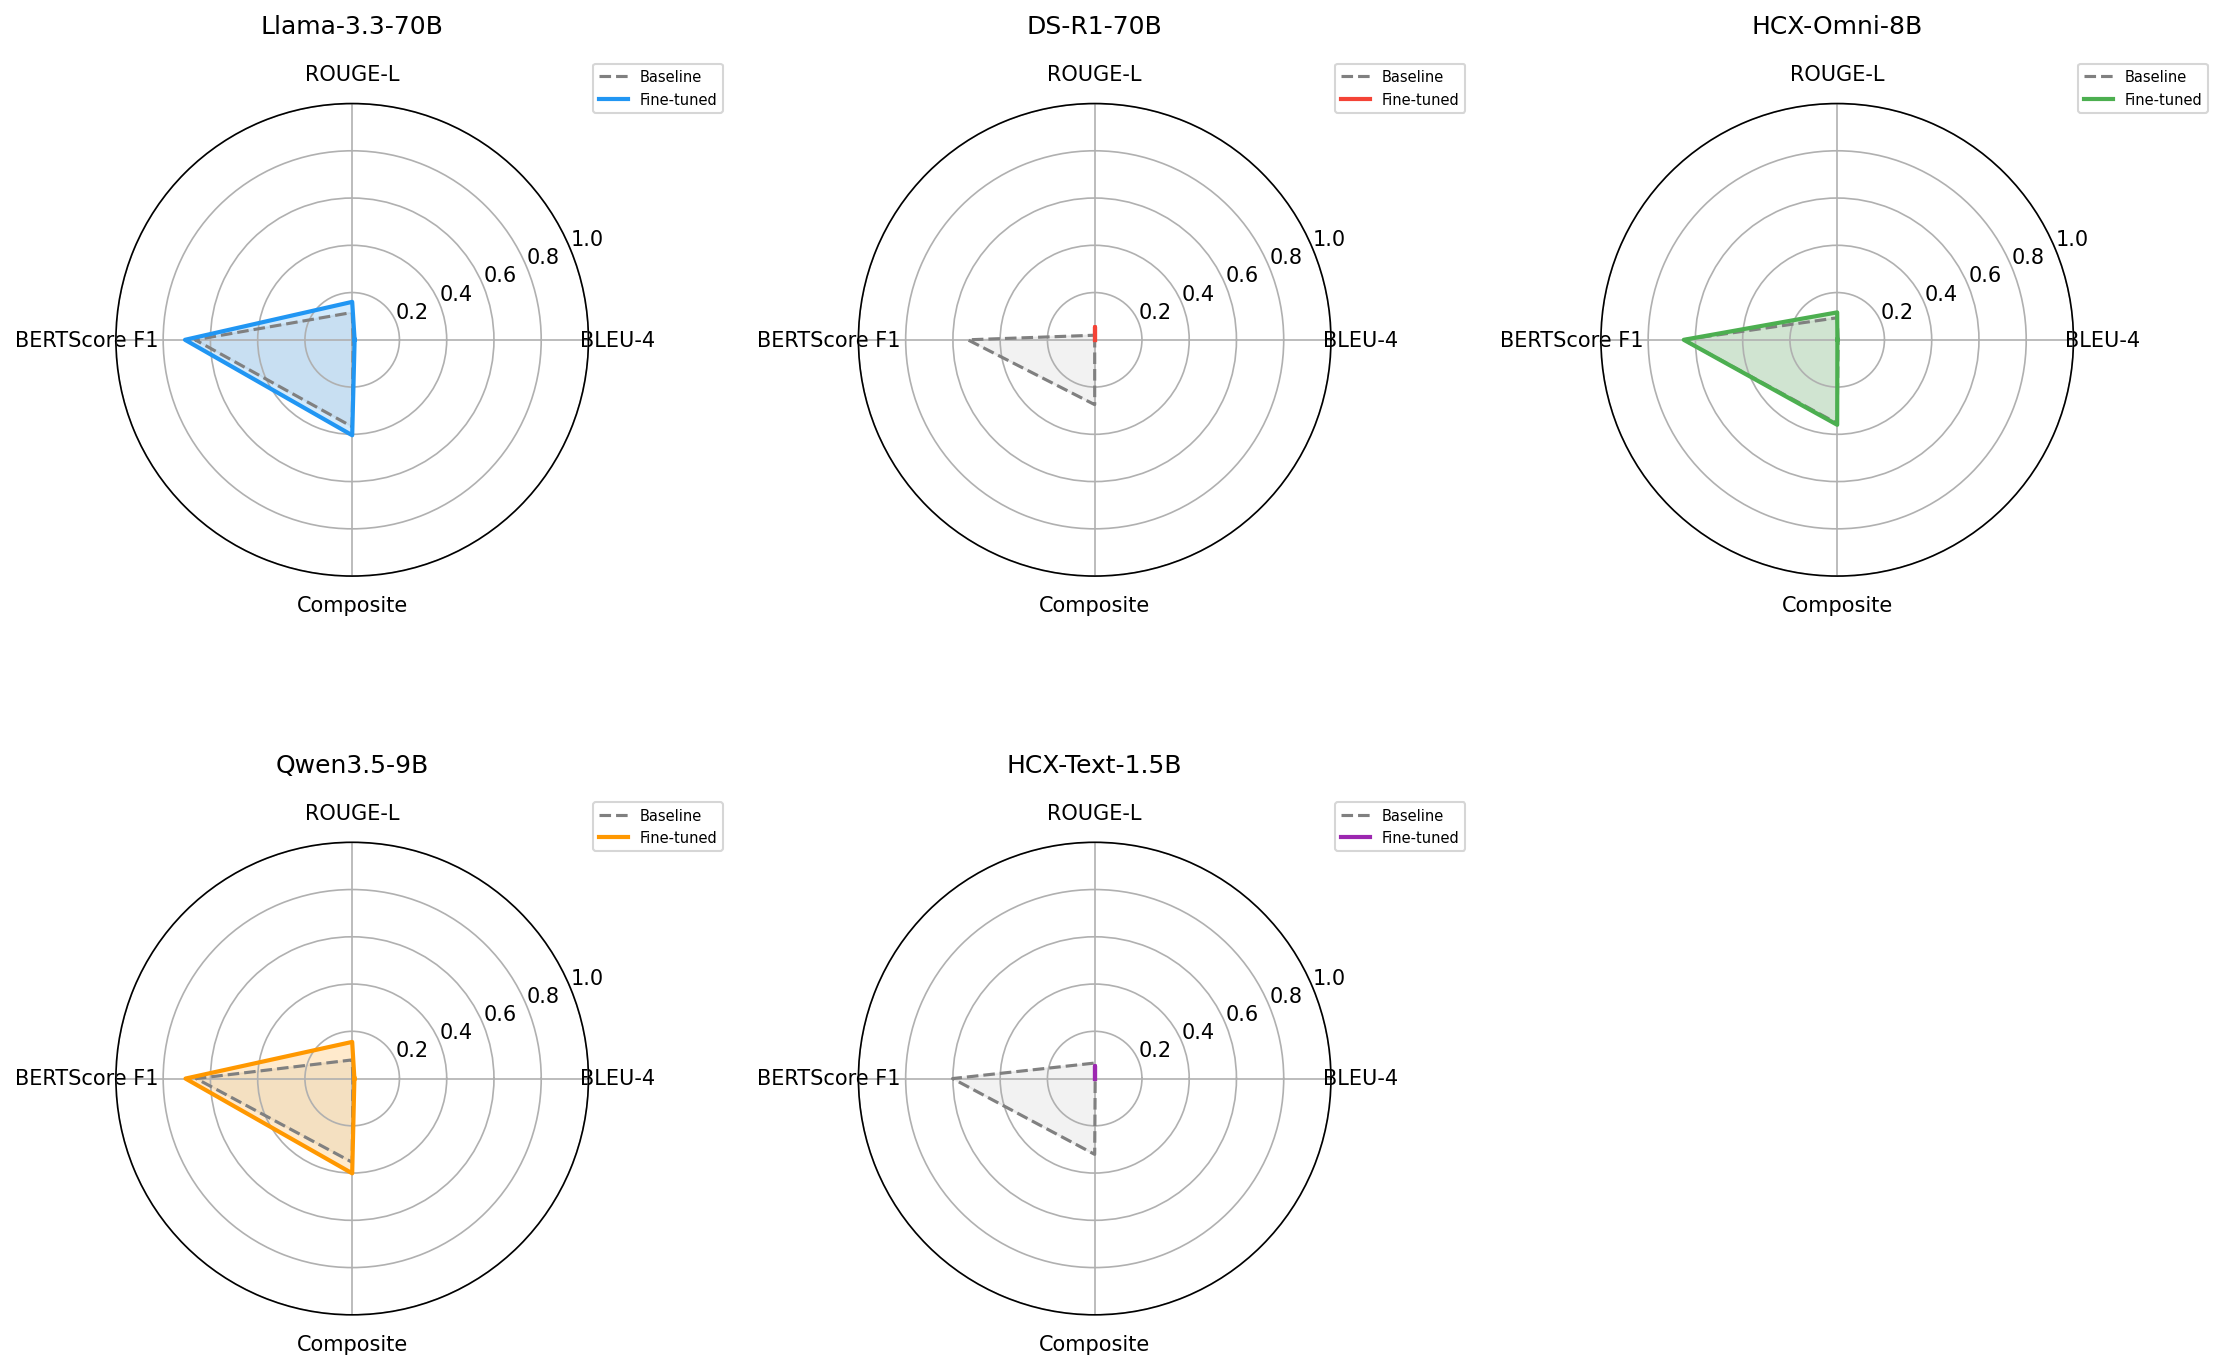
May 7th was the day we synthesized the fine-tuning results of our 5 models (Llama3.3-70B, DSR1-70B, HCX-Omni-8B, Qwen35-9B, HCX-Text-1.5B) and proceeded with full-scale visualization and local environment setup.

[Diário de Bordo Maeumjigi Capstone #13] Limites do Treinamento de 70B & Pivot para Modelos Médios (HCX, Qwen 2.5)

· 3 min para ler
Jaybee
AI & Robotics Engineer

Cover Image

After experiencing the OOM (Out of Memory) hell during the fine-tuning of massive 70B models, on May 4th, we attempted a bold change in strategy. By drastically reducing the batch size, we barely managed to push the 70B models (Llama3.3, DeepSeek-R1) to checkpoint-1200 and 1300, but the training time was absurdly long, resulting in terrible efficiency.

[Diário de Bordo Maeumjigi Capstone #12] Tentativa de Fine-Tuning do Modelo Gigante 70B & A Batalha Contra GPU OOM

· 3 min para ler
Jaybee
AI & Robotics Engineer

Cover Image

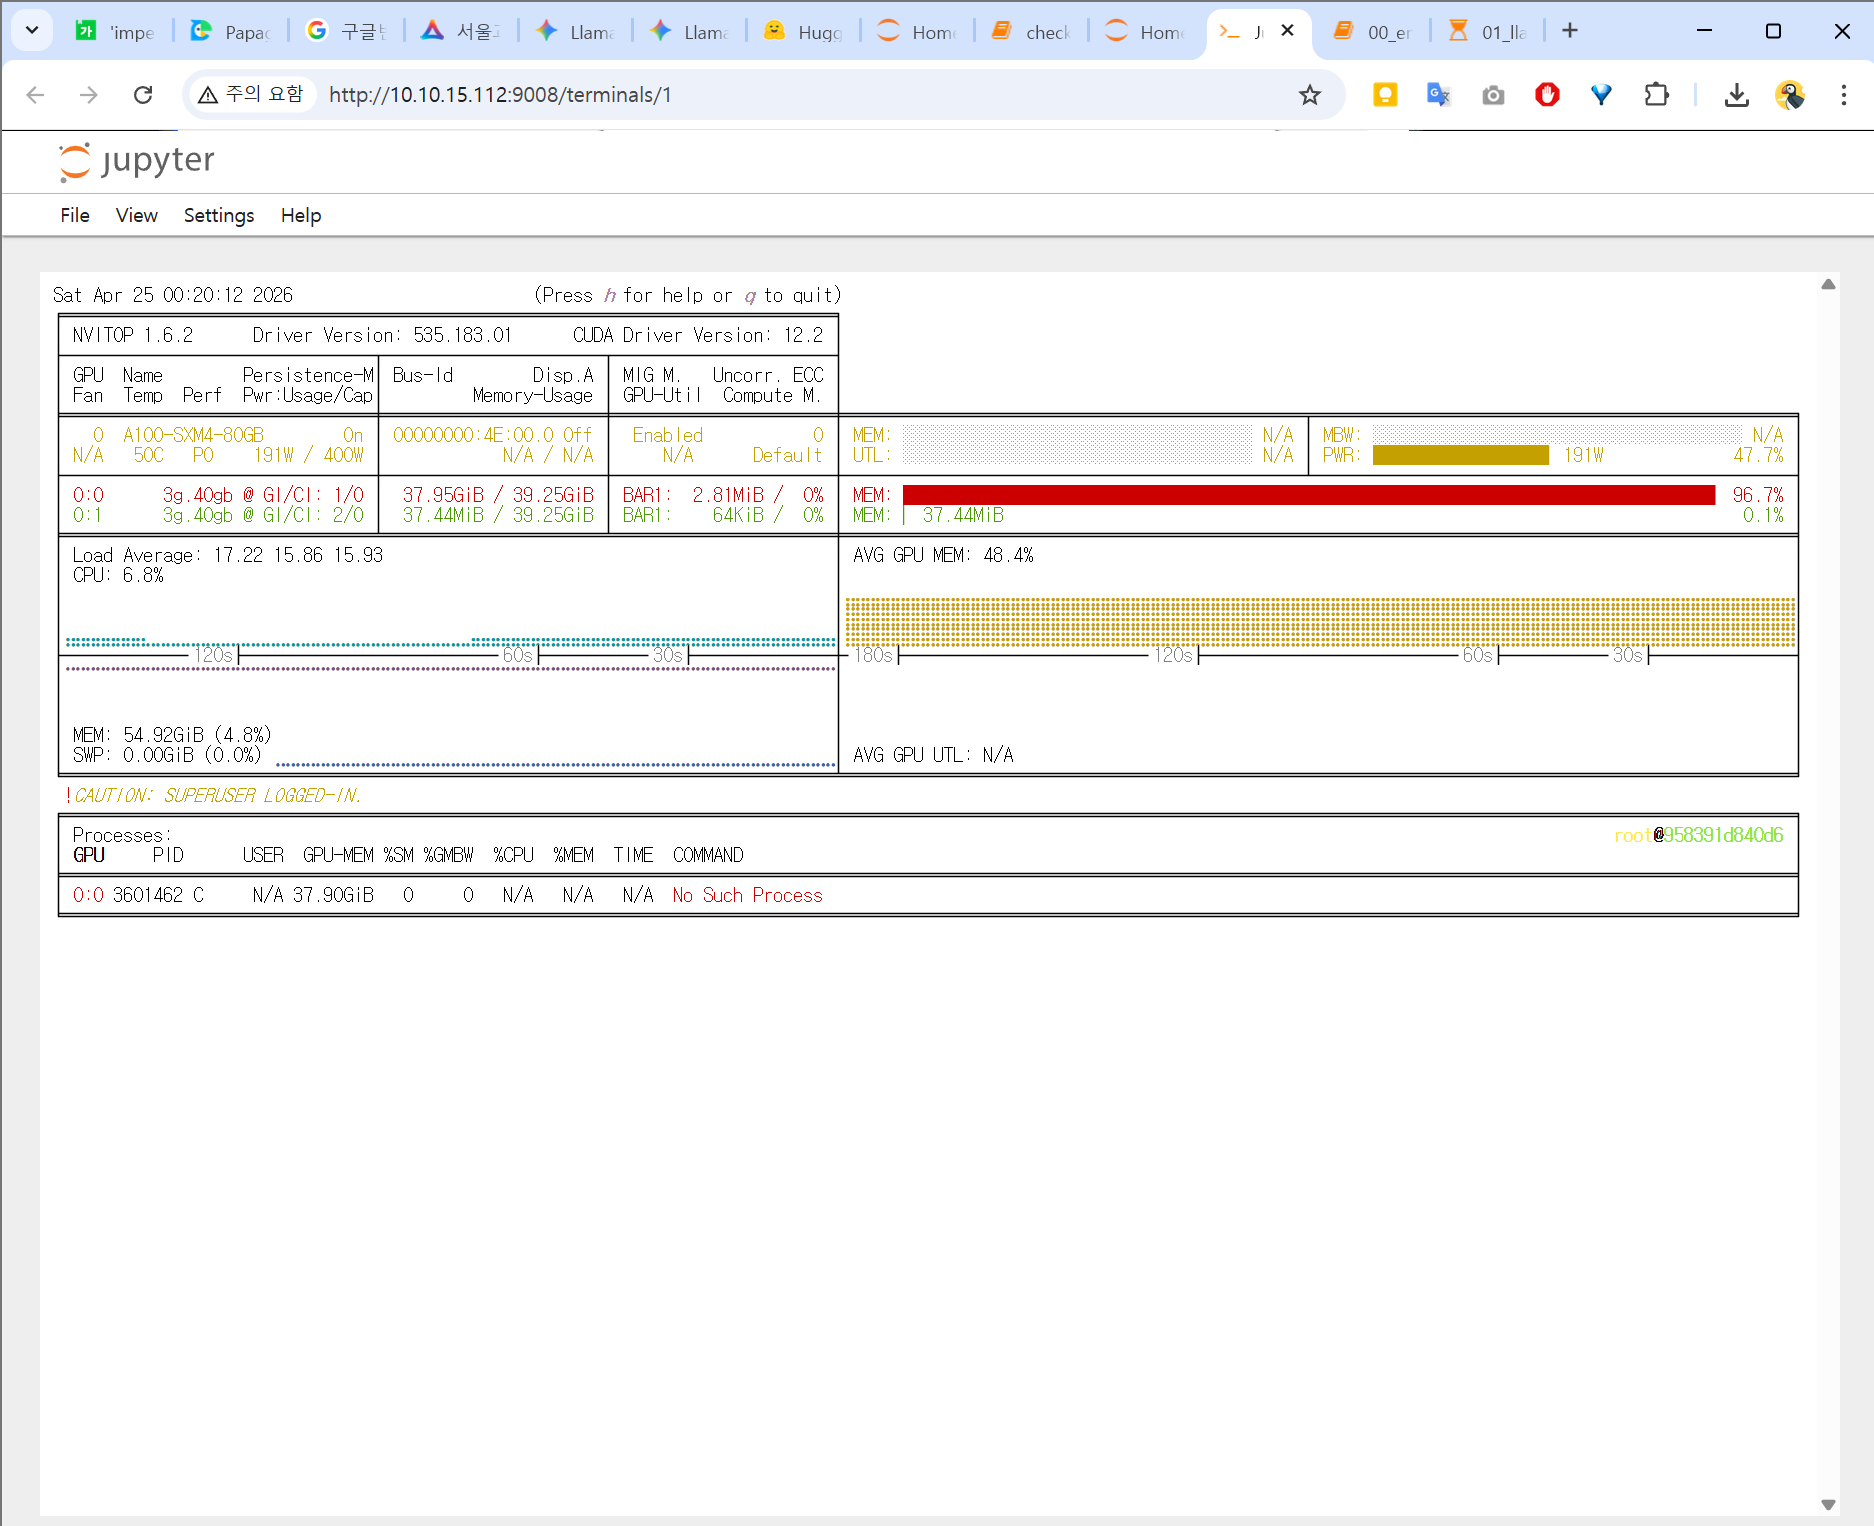
On May 3, having gained enough experience with the 8B models, our team finally challenged the ultimate kings of performance: fine-tuning massive 70B (70 billion parameters) models. We attempted to train both Llama 3.3 70B and DeepSeek-R1 70B, but as expected, we hit a massive hardware resource wall.

[Diário de Bordo Maeumjigi Capstone #9] Depuração de Falhas no Fine-Tuning do Llama 3.1 & Apresentação Intermediária Semana 6

· 3 min para ler
Jaybee
AI & Robotics Engineer

Cover Image

On April 9, using the Colab notebook we ambitiously completed yesterday, we finally attempted the first training (fine-tuning) of our artificial intelligence model (Llama 3.1). However, reality was not that easy, and we had to face numerous errors. It was also a tough day as we had to simultaneously create the presentation materials for the 6th week of the Capstone Design project.

[Diário de Bordo Maeumjigi Capstone #4] Pré-processamento em Larga Escala: Chat-Template do Llama 3.1 & Pipeline JSONL Autônomo

· 4 min para ler
Jaybee
AI & Robotics Engineer

Cover Image

April 1, 2026, was the day our engineering team launched the automated preprocessing pipeline for the massive counseling corpora that would form the foundation of Maeumjigi. Training a high-performance open-source Large Language Model (LLM) like Meta Llama 3.1 requires rigorous data hygiene: converting unstructured multi-party dialogues into clean, token-bounded, and special-token-aligned instruction datasets.