[Maeumjigi 心語伴侶畢業專題開發日誌 #9] Llama 3.1 領域微調實戰排錯與第 6 週中期簡報答辯
· 閱讀時間約 3 分鐘

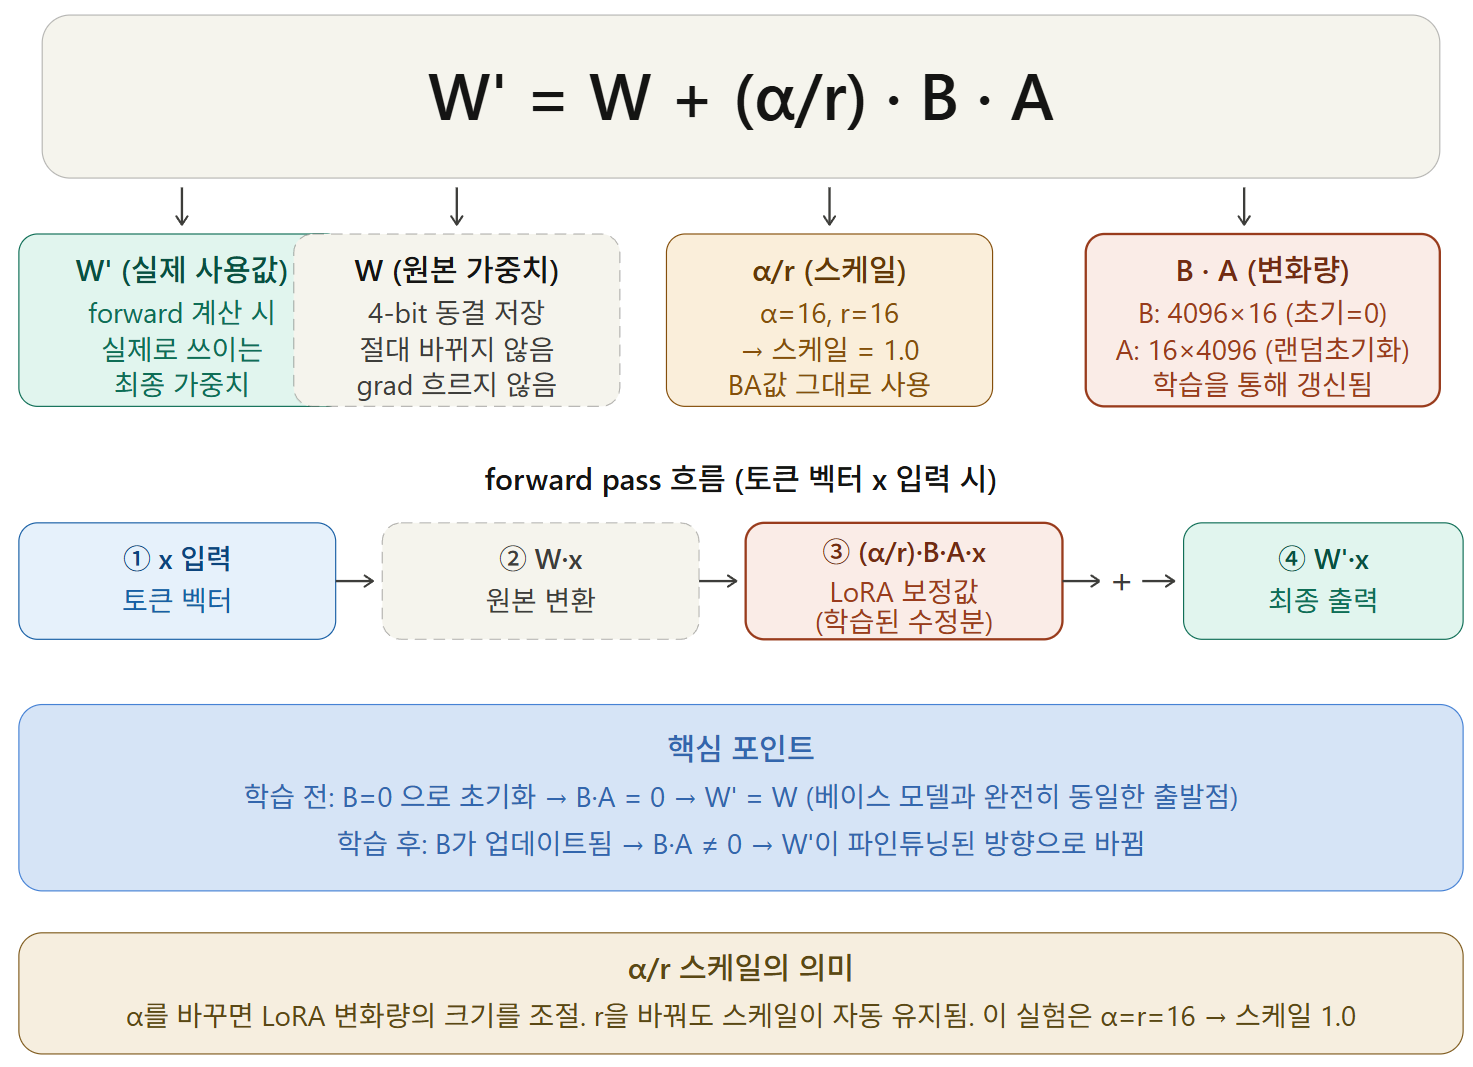
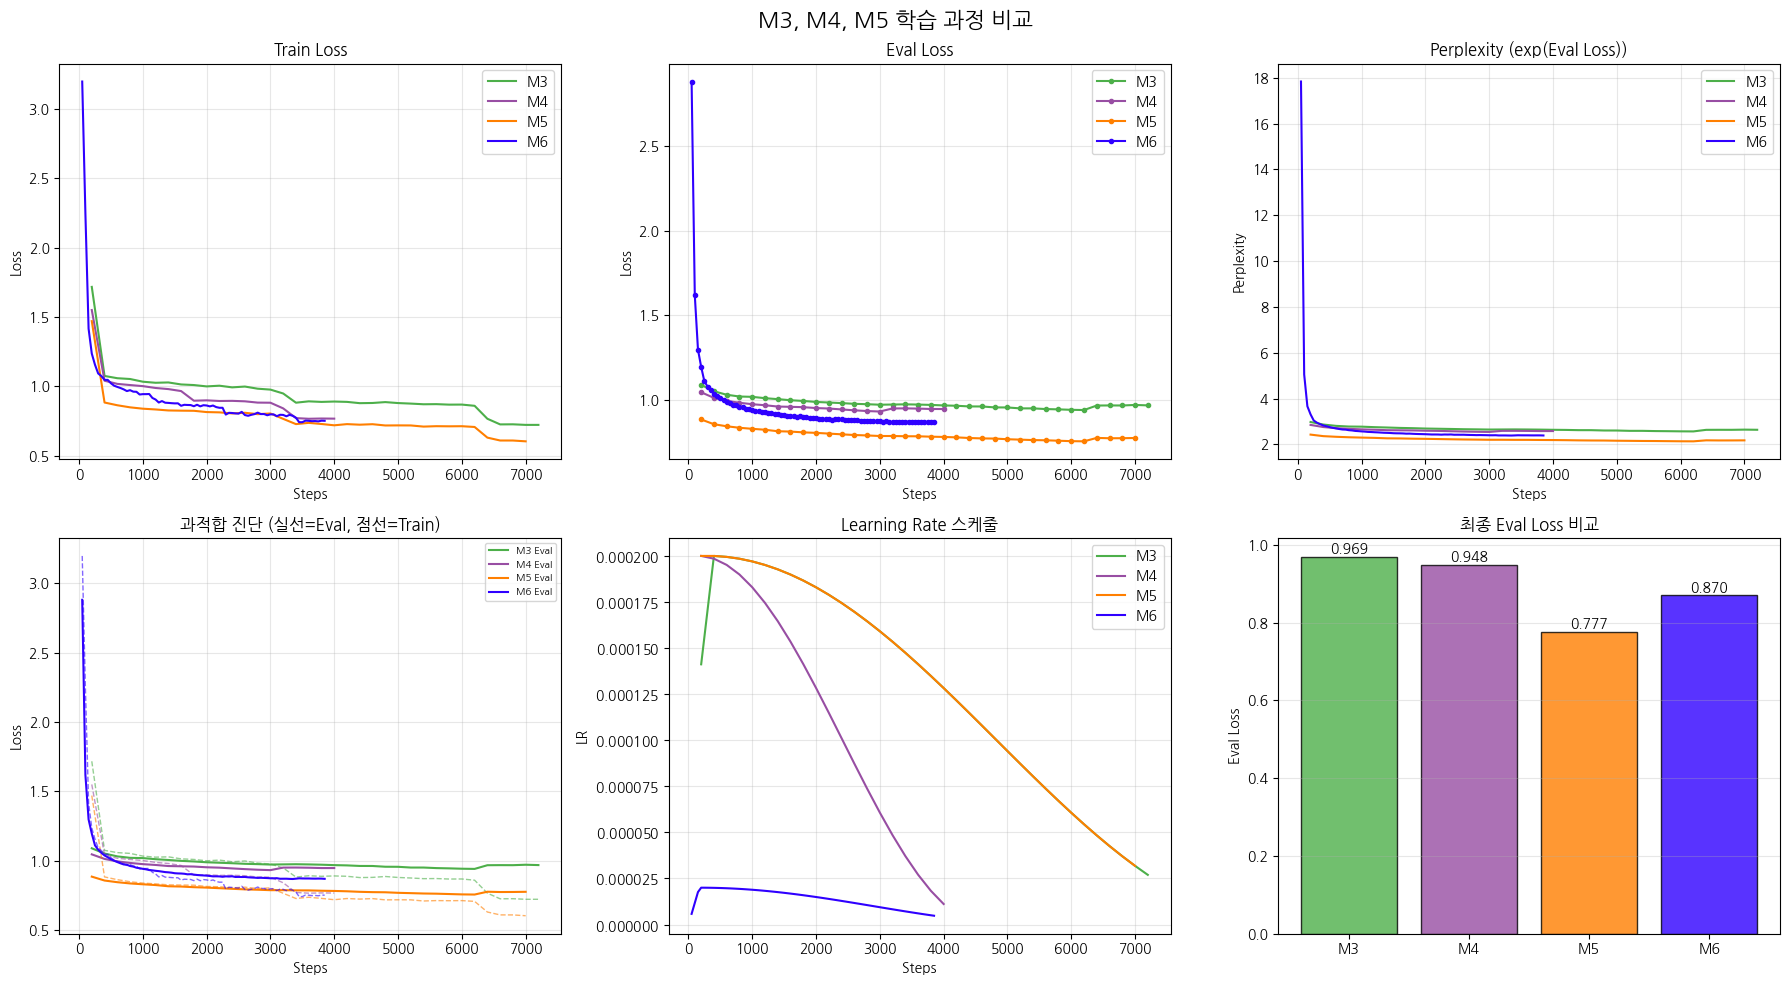
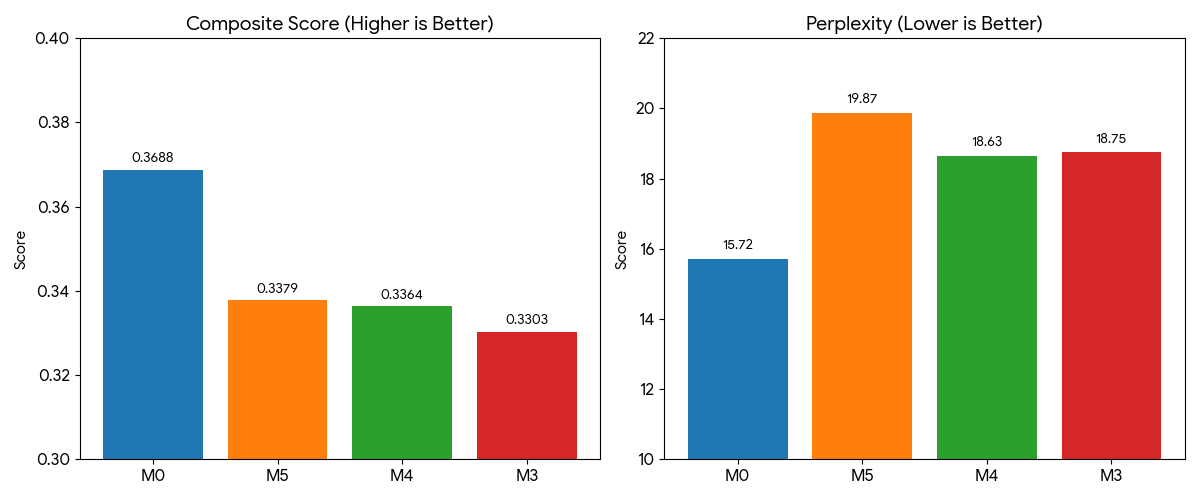
4 月 9 日,依托昨天完成的自動化 Notebook,我們終於迎來了人工智慧大模型 (Llama 3.1) 的首輪正式微調訓練。 然而現實充滿荊棘,無數報錯接踵而至。與此並行的,還有必須在深夜同步趕製第 6 週畢業專題中期簡報資料的極限挑戰。
4 月 9 日,依托昨天完成的自動化 Notebook,我們終於迎來了人工智慧大模型 (Llama 3.1) 的首輪正式微調訓練。 然而現實充滿荊棘,無數報錯接踵而至。與此並行的,還有必須在深夜同步趕製第 6 週畢業專題中期簡報資料的極限挑戰。
4 月 8 日,是我們在推進 Maeumjigi 專案期間經歷的最嚴峻危機,也是令人哭笑不得的技術插曲——Claude API 達到月度配額上限與突發扣費帳單危機。
這是記錄 4 月 3 日的開發實錄。在這一天,我們正式啟動了為深度學習大模型 (Llama 3.1) 餵養高品質心理對話語料的資料深度精煉工程。 這也是我們首次建置起由高級大型語言模型 (Claude) 自主閱讀上下文並高精度標註複雜情緒標籤的龐大管線。
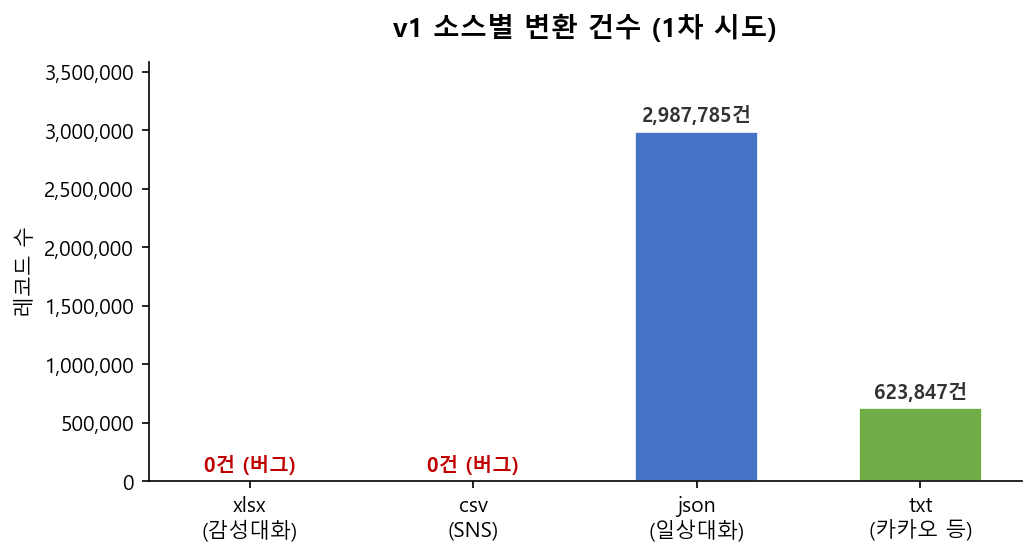
April 1, 2026, was the day our engineering team launched the automated preprocessing pipeline for the massive counseling corpora that would form the foundation of Maeumjigi. Training a high-performance open-source Large Language Model (LLM) like Meta Llama 3.1 requires rigorous data hygiene: converting unstructured multi-party dialogues into clean, token-bounded, and special-token-aligned instruction datasets.
這是記錄 3 月 31 日的開發實錄。在這一天,我們既對國防會議中心預約提醒 App 進行了 Android 端建置測試, 又正式啟動了暗示專案將徹底轉型為前沿 AI 專案的 Llama 3.1 領域微調資料前處理管線。